model fatıgue
First look

Does Haiku 5.5 really cost the same as GPT-6 Luna?

Published 17 Oct 2026Our tests: one painting job, one sorting job

Pressing play loads the video from YouTube (Google), in privacy-enhanced mode. Privacy

This is the video written out, with every figure in full, each linked to its source in the table below.

Three Claudes in fifteen days▶ 0:00

Anthropic released Opus 5.5 on 22 September 2026 and Sonnet 5.5 six days later. Haiku 5.5 followed on 7 October, which makes three new Claude models in fifteen days. Haiku 5.5 is the small, cheap one, and for prompts below a certain size it costs exactly what OpenAI's cheapest GPT-6 model, GPT-6 Luna, costs.

Same price, different bill▶ 0:22

For prompts up to 100K tokens, both charge $0.10 per million input tokens and $0.50 per million output tokens.

Artificial Analysis runs an independent score, the Intelligence Index, built from 10 tests. On it, Haiku 5.5 costs about three times as much per task as GPT-6 Luna at the same effort setting (effort is how hard you ask a model to think). At medium it costs 2.7× as much, at high 2.7×, at xhigh 2.9× and at max 3.1×. At low the gap is wider still, 5.4×: $0.024 a task against Luna's $0.0045. Luna's figure is from Artificial Analysis's full model list of 8 October; the release page we read on 15 October has no row for Luna at low.

Cost per index task at each setting

Same price per token, different bill

GPT-6 LunaHaiku 5.5
US$ per Intelligence Index taskHaiku against Lunalowlow, GPT-6 Luna: $0.0045 · Artificial Analysis, read 8 Oct 2026, 10:14 CEST$0.0045low, Haiku 5.5: $0.0245 · Artificial Analysis, read 15 Oct 2026, 14:17 CEST$0.02455.4×mediummedium, GPT-6 Luna: $0.0175 · Artificial Analysis, read 15 Oct 2026, 14:17 CEST$0.0175medium, Haiku 5.5: $0.0470 · Artificial Analysis, read 15 Oct 2026, 14:17 CEST$0.04702.7×highhigh, GPT-6 Luna: $0.0290 · Artificial Analysis, read 15 Oct 2026, 14:17 CEST$0.0290high, Haiku 5.5: $0.0794 · Artificial Analysis, read 15 Oct 2026, 14:17 CEST$0.07942.7×xhighxhigh, GPT-6 Luna: $0.0422 · Artificial Analysis, read 15 Oct 2026, 14:17 CEST$0.0422xhigh, Haiku 5.5: $0.1238 · Artificial Analysis, read 15 Oct 2026, 14:17 CEST$0.12382.9×maxmax, GPT-6 Luna: $0.0678 · Artificial Analysis, read 15 Oct 2026, 14:17 CEST$0.0678max, Haiku 5.5: $0.2128 · Artificial Analysis, read 15 Oct 2026, 14:17 CEST$0.21283.1×
Artificial Analysis Intelligence Index v4.3.2, API list prices, read 15 October 2026 (GPT-6 Luna at low: 8 October). The ratios are our arithmetic.
The numbers in this chart

The price per token is the same, but Haiku uses far more tokens, reading as well as writing. Over the whole index run at max, it wrote 435.18M output tokens against Luna's 144.38M, about 3.0× as many, and read 7733.95M input tokens against Luna's 3146.39M, 2.5× as many, with each company's own API counting the tokens. At medium Haiku wrote 1.9× as many and read 1.9× as many. Most of each model's cost per task is input: 62% of Haiku's at max. By Artificial Analysis's own cost split, 64% of the gap between the two at medium and 61% at max is input.

The basics▶ 1:02

Haiku 5.5 is Anthropic's small model. Per token it costs 10% of what Haiku 4.5 did, which was $1 per million input tokens and $5 per million output tokens.

Anthropic puts the average saving at around 75%, not 90%. Its footnote gives two reasons. Haiku 5.5 is 90% cheaper than Haiku 4.5 only for requests up to 100K tokens; above that it is 50% cheaper, and 90% of Haiku 4.5's requests were below the line. And Haiku 5.5 has a new tokenizer: according to Anthropic's docs, the same text counts as about 30% more tokens than on Haiku 4.5.

Both models have a context window of about a million tokens: 1,000,000 for Haiku 5.5 and 1,050,000 for GPT-6 Luna. Haiku 5.5 is the first Haiku with effort settings: low, medium, high, xhigh and max, with medium as the default. GPT-6 Luna has the same five plus a setting with no reasoning at all, and Haiku 5.5 can switch its thinking off at high effort or below.

Price per million tokens

API list prices

Haiku 5.5GPT-6 LunaHaiku 4.5
input, prompts up to 100K tokens$0.10$0.10$1
cache read, prompts up to 100K tokens$0.01$0.01
output, prompts up to 100K tokens$0.50$0.50$5
input, prompts over 100K tokens (Haiku 5.5)$0.50$0.10
output, prompts over 100K tokens (Haiku 5.5)$2.50$0.50
input, prompts over 272K tokens$0.50$0.20
output, prompts over 272K tokens$2.50$0.75
Anthropic's pricing page (15 October 2026) and OpenAI's API pricing and GPT-6 Luna pages (15 October 2026), all unchanged on 17 October. Both higher prices apply to the whole request once a prompt is over the line; Anthropic counts cache reads and writes as part of the prompt. Haiku 4.5's cache-read price isn't shown because the video doesn't use it.

On the Intelligence Index, Haiku 4.5 (with reasoning) scored 16.9. Haiku 5.5 scores 34.5 at medium and 43.4 at max. GPT-6 Luna scores 29.9 at medium and 38.1 at max.

Intelligence Index score by setting

Artificial Analysis Intelligence Index v4.3.2

settingHaiku 5.5GPT-6 Luna
low29.521.5
medium34.529.9
high37.832.9
xhigh41.234.6
max43.438.1
no reasoning–18.5
Haiku 4.5, with reasoning16.9
Artificial Analysis, read 15 October 2026 (GPT-6 Luna with no reasoning: 8 October).

Matched by cost, a tie▶ 2:13

Comparing the two at the same setting has a catch, because the same setting doesn't mean the same amount of work. Haiku costs more at each setting, but it also scores higher at each one, so here they are matched by what you pay instead.

Haiku at medium costs $0.047 a task and scores 34.5. GPT-6 Luna at xhigh costs $0.042 and scores 34.6. One step up, Haiku at high costs $0.079 and scores 37.8, and Luna at max costs $0.068 and scores 38.1. Over that stretch, paying about the same gets you about the same score, with Luna a little cheaper.

Matched by cost, a tie

Intelligence Index score against cost per task, each model at every setting. The yellow lines join the two pairs the text compares.

GPT-6 LunaHaiku 5.5
20304050$0.003$0.01$0.03$0.10$0.30GPT-6 Luna at low: score 21.5, $0.0045 per task · Artificial Analysis, read 8 Oct 2026, 10:14 CESTGPT-6 Luna at medium: score 29.9, $0.0175 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTGPT-6 Luna at high: score 32.9, $0.0290 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTGPT-6 Luna at xhigh: score 34.6, $0.0422 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTGPT-6 Luna at max: score 38.1, $0.0678 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTGPT-6 LunaHaiku 5.5 at low: score 29.5, $0.0245 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTlowHaiku 5.5 at medium: score 34.5, $0.0470 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTmediumHaiku 5.5 at high: score 37.8, $0.0794 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESThighHaiku 5.5 at xhigh: score 41.2, $0.1238 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTxhighHaiku 5.5 at max: score 43.4, $0.2128 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTmaxHaiku 5.5scorecost per task, log scale
20304050$0.003$0.01$0.03$0.10$0.30GPT-6 Luna at low: score 21.5, $0.0045 per task · Artificial Analysis, read 8 Oct 2026, 10:14 CESTGPT-6 Luna at medium: score 29.9, $0.0175 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTGPT-6 Luna at high: score 32.9, $0.0290 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTGPT-6 Luna at xhigh: score 34.6, $0.0422 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTGPT-6 Luna at max: score 38.1, $0.0678 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTGPT-6 LunaHaiku 5.5 at low: score 29.5, $0.0245 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTHaiku 5.5 at medium: score 34.5, $0.0470 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTHaiku 5.5 at high: score 37.8, $0.0794 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTHaiku 5.5 at xhigh: score 41.2, $0.1238 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTHaiku 5.5 at max: score 43.4, $0.2128 per task · Artificial Analysis, read 15 Oct 2026, 14:17 CESTHaiku 5.5scorecost per task, log scale
Artificial Analysis Intelligence Index v4.3.2, API list prices, read 15 October 2026 (GPT-6 Luna at low: 8 October).
The numbers in this chart
settingGPT-6 Luna scoreGPT-6 Luna cost per index taskHaiku 5.5 scoreHaiku 5.5 cost per index task
low21.5$0.004529.5$0.0245
medium29.9$0.017534.5$0.0470
high32.9$0.029037.8$0.0794
xhigh34.6$0.042241.2$0.1238
max38.1$0.067843.4$0.2128

They come apart at the top. Luna's best score is at max, 38.1. Haiku at max reaches 43.4, for $0.213 a task, 3.1× what Luna costs at max.

The two tables below have the figures from Artificial Analysis that the video uses, at every setting, as we read them for the video. Its other test scores are on its release page.

Artificial Analysis, Haiku 5.5 at every setting

As read for the video

settingIntelligence Indexcost per index taskoutput tokens, index runAA-Omniscience righthallucination rateOmniscience indexTerminal-Bench 4.0
low29.5$0.024532,289,69433.2%44.9%+3.2512.6%
medium34.5$0.047053,785,05734.0%44.8%+4.4715.2%
high37.8$0.079497,096,31834.8%44.5%+5.7521.7%
xhigh41.2$0.1238179,986,85834.9%44.4%+6.0529.3%
max43.4$0.2128435,183,28636.4%40.4%+10.6732.8%
Artificial Analysis, Intelligence Index v4.3.2, read 15 October 2026; re-read 17 October, every value in this table unchanged. Cost per task at API list prices; output tokens as Anthropic's API counts them. The hallucination rate is the share of wrong answers among the questions a model didn't get right.

Artificial Analysis, GPT-6 Luna at every setting

As read for the video

settingIntelligence Indexcost per index taskoutput tokens, index runAA-Omniscience righthallucination rateOmniscience indexTerminal-Bench 4.0
low21.5$0.0045––––0.0%
medium29.9$0.017528,532,18343.1%84.7%−5.052.5%
high32.9$0.029046,829,42842.8%84.4%−5.504.5%
xhigh34.6$0.042268,515,55644.2%82.4%−1.838.1%
max38.1$0.0678144,380,99443.8%76.7%+0.6512.6%
Same source and read. Output tokens as OpenAI's API counts them. GPT-6 Luna at low isn't on Artificial Analysis's release page: its score and cost are from Artificial Analysis's full list of 8 October, and its Terminal-Bench figure from the data API of 15 October. With no reasoning, GPT-6 Luna scores 18.5 at $0.0113 a task (8 October). Speeds are in the speed table further down.

The painting test▶ 3:10

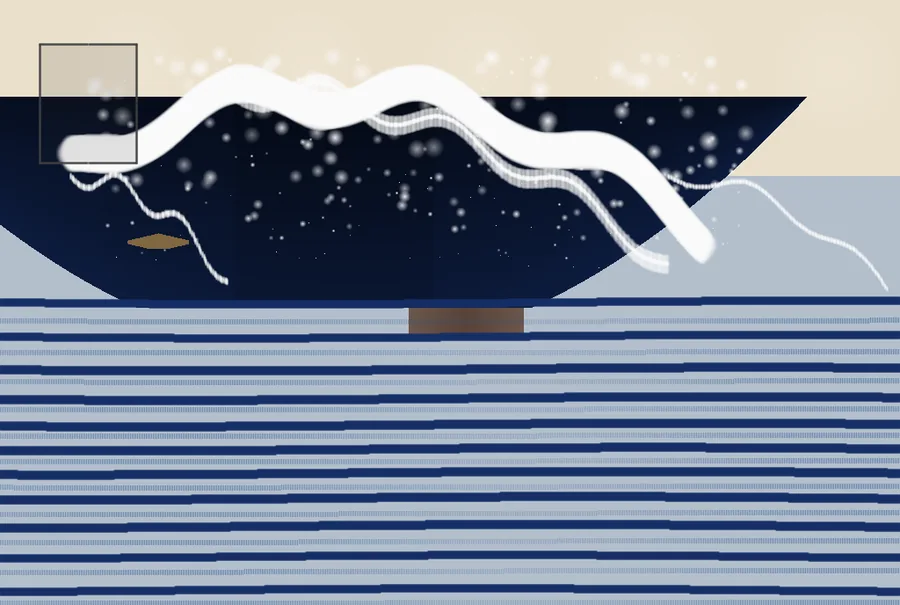
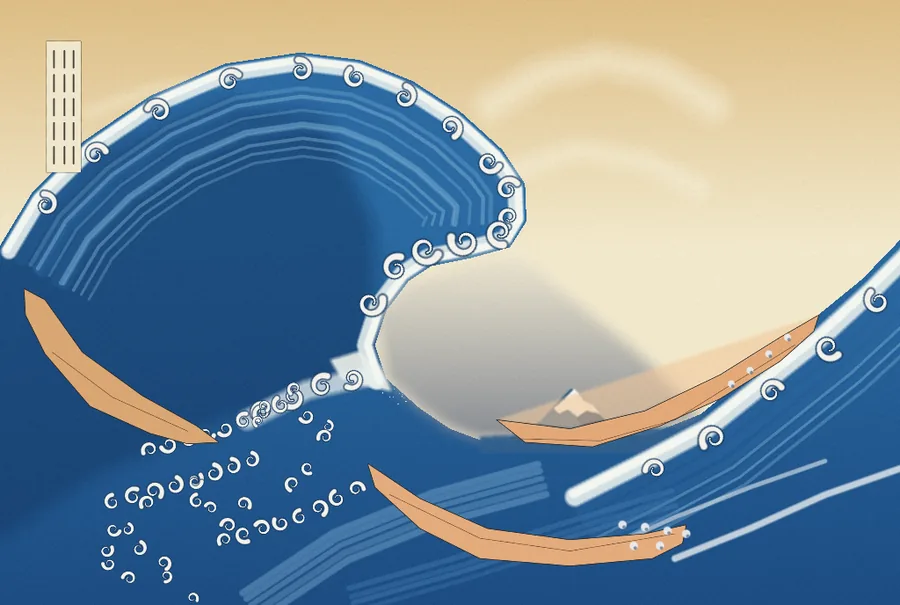
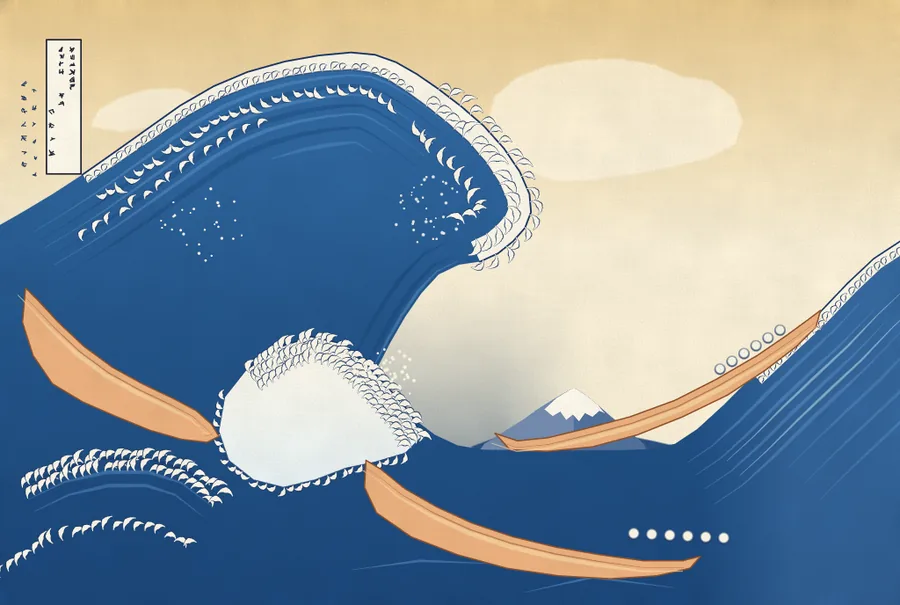
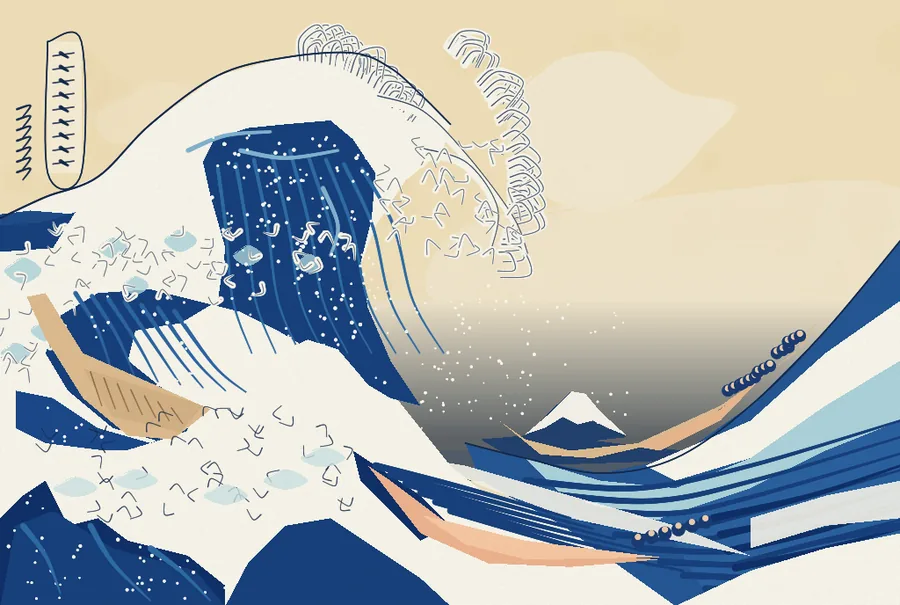
This is the test we run on new models. Each one looks at Hokusai's Great Wave and paints it by writing a painting program, with no image model and no image library. We ran each model once at each setting shown.

Haiku 4.5 didn't paint a wave at all. Haiku 5.5 at medium painted a recognisable Great Wave, with the curling crest, the boats and Mount Fuji, in 329 s for $0.04 at API prices. At max it took 859 s and cost $0.77. It used more tokens, and its context grew past 100K tokens, where the price goes up (the section on the 100K-token step below has the arithmetic). To our eye that painting isn't clearly better. GPT-6 Luna at max painted the wave too, in 317 s, flatter and with more empty sky; Codex doesn't report a dollar cost for it. Sonnet 5.5 and Opus 5.5, painted on 28 September, are still the most detailed.

Five models, six runs, one prompt: the Great Wave
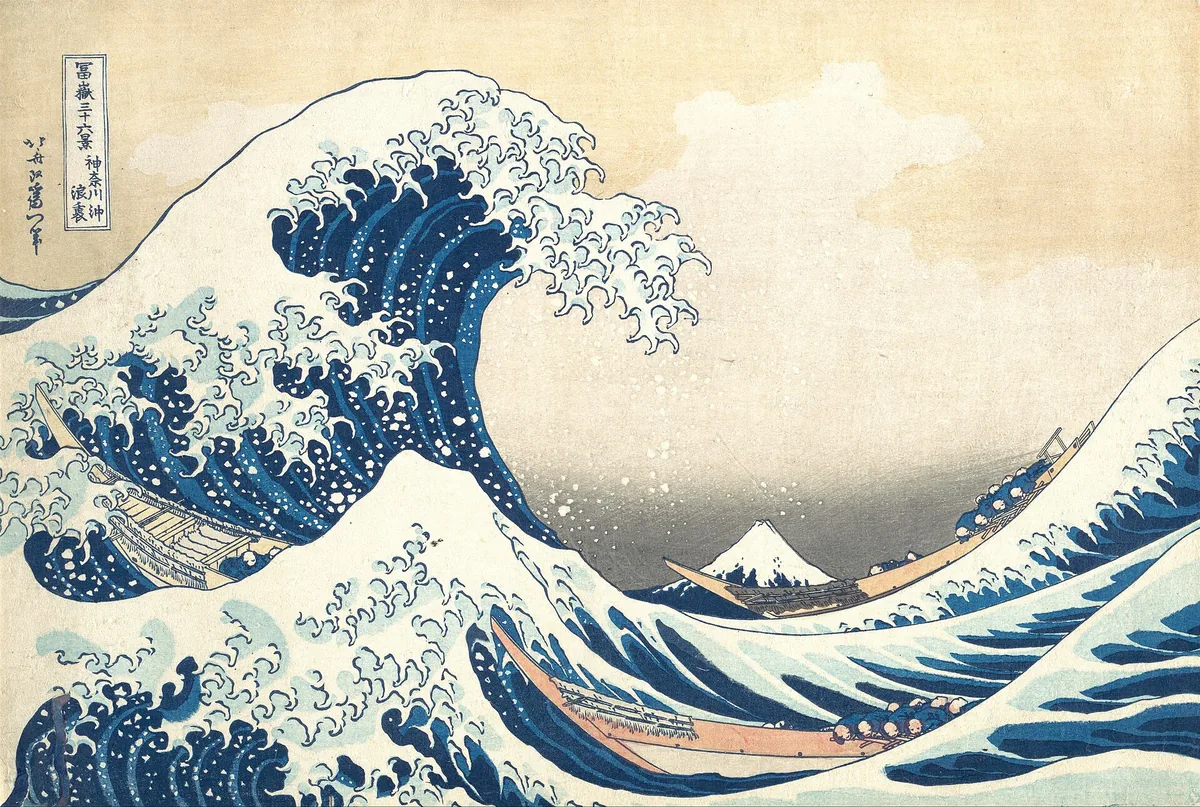
Hokusai's print, the Great Wave
The printKatsushika Hokusai, Under the Wave off Kanagawa (The Great Wave), c. 1830–32. The Metropolitan Museum of Art, H. O. Havemeyer Collection, Bequest of Mrs. H. O. Havemeyer, 1929 (JP1847). Public domain.
Haiku 4.5's attempt: a dark band, a white squiggle and stripes, no wave
Haiku 4.5Claude Code · default · 1 run
379 s · $0.33 at API prices
Haiku 5.5's painting of the Great Wave
Haiku 5.5Claude Code · medium · 1 run
329 s · $0.04 at API prices
Haiku 5.5's painting of the Great Wave
Haiku 5.5Claude Code · max · 1 run
859 s · $0.77 at API prices, crossed the 100K line
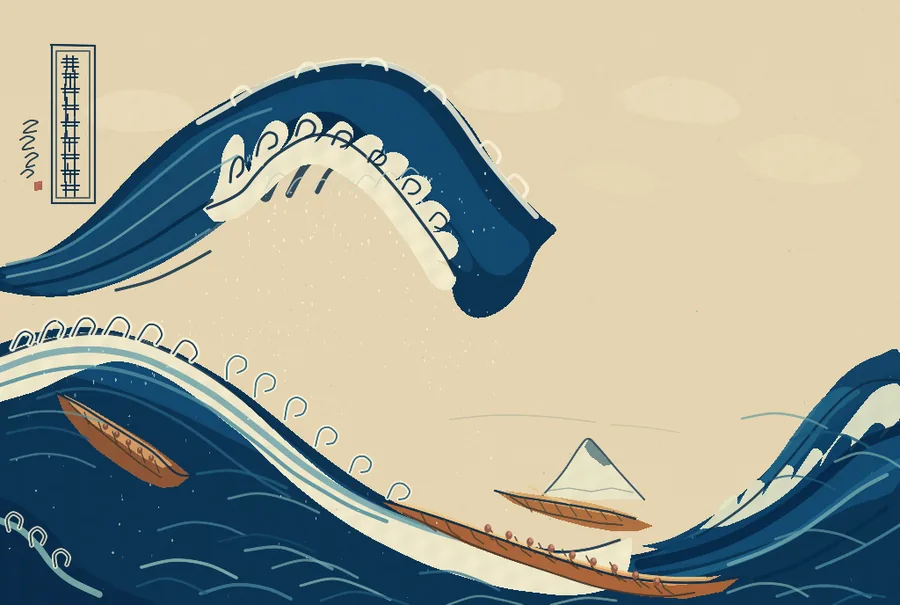
GPT-6 Luna's painting of the Great Wave
GPT-6 LunaCodex · max · 1 run
317 s · Codex plan, no dollar figure
Sonnet 5.5's painting of the Great Wave
Sonnet 5.5Claude Code · default · 28 Sep · 1 run
98 s · $0.21 at API prices
Opus 5.5's painting of the Great Wave
Opus 5.5Claude Code · default · 28 Sep · 1 run
327 s · $1.03 at API prices
Our runs, one per model and setting, on 10 October 2026 (Sonnet 5.5 and Opus 5.5: 28 September 2026). Times are agent time; costs are Claude Code's own list-price figure.

These are single runs, so they show what each model can do, not how often it does it.

Where Luna is the better buy▶ 4:11

For its Coding Agents board, Artificial Analysis runs models inside coding tools, Haiku 5.5 in Claude Code and GPT-6 Luna in Codex, and averages three tests. Haiku's best score there is 41.4, at xhigh, for $0.61 a task. Luna at max scores 41.1 for $0.18. That is about the same score for 0.29× the cost, under a third.

Luna draws level thanks to one of the three tests, a set of software engineering tasks called DeepSWE, where Luna at max gets 63.7% against Haiku at xhigh's 49.0%. Haiku is ahead on the other two. Turning Haiku up to max makes it worse overall on this board: 36.5, at $2.58 a task.

Coding Agents board, the two rows compared

GPT-6 Luna at max in Codex, Haiku 5.5 at xhigh in Claude Code

GPT-6 Luna, maxHaiku 5.5, xhigh
scoreindex (average)index (average), GPT-6 Luna, max: 41.1 · Artificial Analysis, read 15 Oct 2026, 09:02 CEST41.1index (average), Haiku 5.5, xhigh: 41.4 · Artificial Analysis, read 15 Oct 2026, 09:02 CEST41.4DeepSWE v1.1DeepSWE v1.1, GPT-6 Luna, max: 63.7% · Artificial Analysis, read 15 Oct 2026, 09:02 CEST63.7%DeepSWE v1.1, Haiku 5.5, xhigh: 49.0% · Artificial Analysis, read 15 Oct 2026, 09:02 CEST49.0%SWE-Atlas-QnASWE-Atlas-QnA, GPT-6 Luna, max: 44.4% · Artificial Analysis, read 15 Oct 2026, 09:02 CEST44.4%SWE-Atlas-QnA, Haiku 5.5, xhigh: 51.6% · Artificial Analysis, read 15 Oct 2026, 09:02 CEST51.6%Terminal-Bench 4.0Terminal-Bench 4.0, GPT-6 Luna, max: 15.2% · Artificial Analysis, read 15 Oct 2026, 09:02 CEST15.2%Terminal-Bench 4.0, Haiku 5.5, xhigh: 23.7% · Artificial Analysis, read 15 Oct 2026, 09:02 CEST23.7%
Artificial Analysis Coding Agents board, read 15 October 2026. Cost per task: $0.176 and $0.610.
The numbers in this chart
GPT-6 Luna, maxHaiku 5.5, xhigh
index (average)41.141.4
DeepSWE v1.163.7%49.0%
SWE-Atlas-QnA44.4%51.6%
Terminal-Bench 4.015.2%23.7%

Artificial Analysis Coding Agents board

Each model inside a coding tool; the index is the average of three tests

indexcost per taskDeepSWE v1.1SWE-Atlas-QnATerminal-Bench 4.0
Haiku 5.5 at low, Claude Code28.2$0.14345.4%33.1%6.1%
Haiku 5.5 at medium, Claude Code33.6$0.22647.5%41.7%11.6%
Haiku 5.5 at high, Claude Code35.1$0.36546.3%46.2%12.6%
Haiku 5.5 at xhigh, Claude Code41.4$0.61049.0%51.6%23.7%
Haiku 5.5 at max, Claude Code36.5$2.58046.0%33.6%29.8%
GPT-6 Luna at max, Codex41.1$0.17663.7%44.4%15.2%
Artificial Analysis, read 15 October 2026; re-read 17 October, every row unchanged. DeepSWE is a set of software engineering tasks, SWE-Atlas-QnA technical questions about a codebase. GPT-6 Luna at max in Codex is its only single-model row. Marked: the two rows the video compares.

Then a test of our own, one job with one run per setting. We gave both models 610 real messages sent through a tutoring business's website contact form. Simple keyword rules had already labelled them: 128 genuine inquiries and 482 spam. Those labels are sometimes wrong themselves, so what we measured is how often each model agrees with them. We ran each model at low and at medium and kept its better result.

GPT-6 Luna at low agreed with the labels on 88.9% of the messages and Haiku 5.5 at medium on 82.0%. Message by message, that is a difference of +6.9 points, with a 95% interval from +4.4 to +9.3. By the labels, Haiku let 103 spam messages through and Luna 57, though Luna marked 11 genuine ones as spam, to Haiku's 7. Luna cost $0.081 per thousand messages and Haiku $0.176.

Our contact-form test, all four settings

610 messages labelled by keyword rules: 128 genuine, 482 spam. One run per setting, 8 October 2026

agrees with the labelsspam let throughgenuine marked as spaminput tokens per messageoutput tokens per messagecost per thousand messagesmedian time per message
GPT-6 Luna at low88.9%571140981$0.0812.30 s
GPT-6 Luna at medium88.4%6011409131$0.1062.82 s
Haiku 5.5 at medium82.0%1037775198$0.1761.70 s
Haiku 5.5 at low79.2%1198775115$0.1351.53 s
Ours. The messages are every submission to a tutoring and coaching business's website form that was copied into its CRM, from a census of 5 September 2026 (128 labelled real, 482 likely spam; staff and unsure rows dropped, 610 scored); the labels come from keyword rules, so this measures agreement with them, not correctness. Cost is each setting's average tokens at both models' list price ($0.10 in, $0.50 out per million). Paired difference, GPT-6 Luna at low minus Haiku 5.5 at medium: +6.9 points (95% interval +4.4 to +9.3), from a bootstrap over the same messages. Marked: each model's better setting.

Each model's other setting did no better. Haiku at low minus Haiku at medium comes to −2.8 points (95% interval −5.1 to −0.7). Luna at low and at medium were within a point of each other: low minus medium is +0.5 points (interval −0.7 to +1.6). Haiku read more input tokens per message (775 against Luna's 409) and wrote more (198 against 81), which is where its higher cost comes from.

Where Haiku is ahead▶ 5:48

Artificial Analysis also runs a knowledge test, AA-Omniscience, which takes points off for a wrong answer and none for saying "I don't know". From medium to max, Luna knows more: it gets 42.8% to 44.2% of the questions right, Haiku 34.0% to 36.4%.

When a model doesn't have the right answer, though, Haiku makes one up 40.4% to 44.8% of the time, and Luna 76.7% to 84.7% of the time. So when it doesn't know, Haiku makes things up about half as often, because more often it gives no answer or only part of one. At max, Haiku answers 36.4% right, 25.7% wrong and leaves 37.9% unanswered or partly answered; Luna answers 43.8% right, 43.1% wrong and leaves 13.1%. On the test's own score, right answers minus wrong ones, Haiku comes out ahead: +10.67 at max against Luna's +0.65.

When it doesn't know, how often it makes something up

AA-Omniscience hallucination rate: wrong answers among the questions a model didn't get right

GPT-6 LunaHaiku 5.5
hallucination ratemediummedium, GPT-6 Luna: 84.7% · Artificial Analysis, read 15 Oct 2026, 14:17 CEST84.7%medium, Haiku 5.5: 44.8% · Artificial Analysis, read 15 Oct 2026, 14:17 CEST44.8%highhigh, GPT-6 Luna: 84.4% · Artificial Analysis, read 15 Oct 2026, 14:17 CEST84.4%high, Haiku 5.5: 44.5% · Artificial Analysis, read 15 Oct 2026, 14:17 CEST44.5%xhighxhigh, GPT-6 Luna: 82.4% · Artificial Analysis, read 15 Oct 2026, 14:17 CEST82.4%xhigh, Haiku 5.5: 44.4% · Artificial Analysis, read 15 Oct 2026, 14:17 CEST44.4%maxmax, GPT-6 Luna: 76.7% · Artificial Analysis, read 15 Oct 2026, 14:17 CEST76.7%max, Haiku 5.5: 40.4% · Artificial Analysis, read 15 Oct 2026, 14:17 CEST40.4%
Artificial Analysis, read 15 October 2026. GPT-6 Luna at low and with no reasoning have no AA-Omniscience figures on the page.
The numbers in this chart
GPT-6 LunaHaiku 5.5
medium84.7%44.8%
high84.4%44.5%
xhigh82.4%44.4%
max76.7%40.4%

Haiku also leads on Terminal-Bench 4.0, a set of tasks done at a command line. At max it passes 32.8% of them in Artificial Analysis's run and 36.36% in Vals's, another independent tester, which also runs both models at max; Luna passes 12.6% and 13.64%. Artificial Analysis gives every model the same basic agent setup for this test. Terminal-Bench is also one of the three tests on the Coding Agents board, and Haiku leads it there too, inside the coding tools: 23.7% at xhigh and 29.8% at max, against Luna's 15.2%. So Luna's tie on coding comes from the software engineering tasks, not from command-line work.

Terminal-Bench 4.0, three ways

Share of command-line tasks passed

GPT-6 Luna, maxHaiku 5.5
share of tasks passedAA, both at maxAA, both at max, GPT-6 Luna, max: 12.6% · Artificial Analysis, read 15 Oct 2026, 14:17 CEST12.6%AA, both at max, Haiku 5.5: 32.8% · Artificial Analysis, read 15 Oct 2026, 14:17 CEST32.8%ValsVals, GPT-6 Luna, max: 13.6% · Vals, read 15 Oct 2026, 09:18 CEST13.6%Vals, Haiku 5.5: 36.4% · Vals, read 15 Oct 2026, 09:18 CEST36.4%in the tools, Haiku xhighin the tools, Haiku xhigh, GPT-6 Luna, max: 15.2% · Artificial Analysis, read 15 Oct 2026, 09:02 CEST15.2%in the tools, Haiku xhigh, Haiku 5.5: 23.7% · Artificial Analysis, read 15 Oct 2026, 09:02 CEST23.7%in the tools, Haiku maxin the tools, Haiku max, GPT-6 Luna, max: 15.2% · Artificial Analysis, read 15 Oct 2026, 09:02 CEST15.2%in the tools, Haiku max, Haiku 5.5: 29.8% · Artificial Analysis, read 15 Oct 2026, 09:02 CEST29.8%
Artificial Analysis (AA: its release page, and its Coding Agents board, where Luna runs in Codex and Haiku in Claude Code) and Vals, read 15 October 2026. Vals runs both models at max; AA's first row uses the same basic agent for every model.
The numbers in this chart
GPT-6 Luna, maxHaiku 5.5
AA, both at max12.6%32.8%
Vals13.6%36.4%
in the tools, Haiku xhigh15.2%23.7%
in the tools, Haiku max15.2%29.8%

Vals runs many more tests than the video had time for. Here is every one it lists for both models.

Every benchmark Vals lists for both models

Accuracy with Vals's own ± interval

Vals benchmarkClaude Haiku 5.5 at maxGPT-6 Luna at max
Vals Index54.44% ±1.4151.22% ±1.07
Code Migration44.57% ±4.2342.55% ±4.42
CyberBench v1.175.48% ±5.2176.25% ±5.29
EMB59.02% ±4.1768.52% ±2.81
Finance Agent (v2)54.14% ±2.1349.87% ±0.23
Legal Research Bench43.27% ±3.4430.29% ±3.19
MedCode51.54% ±2.1744.69% ±2.30
MedScribe89.54% ±1.9283.71% ±1.95
MysteryMechanism35.13% ±3.2119.37% ±2.66
ProofBench v1.189.00% ±3.1564.00% ±4.82
SAGE45.78% ±3.4248.09% ±3.38
Public Benefits Bench v1.163.19% ±1.2557.65% ±1.28
SRE Bench5.72% ±1.442.67% ±1.00
Tax Agent Bench31.92% ±3.3519.95% ±2.87
Vibe Code Bench 1-10020.41% ±3.79not listed
Vibe Code Bench v1.190.44% ±1.7381.65% ±3.38
BioMysteryBench70.37% ±1.3361.48% ±2.59
Harvey's Legal Agent Benchmark1.25% ±0.722.92% ±1.36
IOI47.28% ±10.7255.56% ±8.87
ProgramBench2.50% ±1.110.50% ±0.50
SWE-bench Multimodal43.96% ±2.2737.50% ±2.21
Terminal-Bench 4.036.36% ±2.3113.64% ±1.51
Terminal-Bench Science10.00% ±3.614.29% ±2.44
Vals Science Index (added by 17 October)38.50% ±1.6728.38% ±1.48
Vals Index, cost per test$3.000$0.431
Vals, read 15 October 2026. Vals ran both models at max effort. Re-read 17 October: every value and interval unchanged, and one new row, the Vals Science Index. Marked: the row the video uses. "Not listed": the benchmark isn't on GPT-6 Luna's Vals page.

On computer use, Anthropic's own numbers give Haiku a partial-credit score of 72.4% on a subset of 82 OSWorld 2.1 tasks and Luna 48.9%, both at max. Anthropic ran Luna itself, through OpenAI's API. Counting only tasks finished completely, Haiku's pass rate is 37.1%.

Haiku also streams its words faster than Luna, but it writes more, and at max it waits much longer before it starts. The video showed Artificial Analysis's figures as we read them on 15 October: at max, Haiku wrote 240now 243 tokens a second and Luna 128now 132, and Haiku took 237 snow 267 s to its first token against Luna's 90 snow 116 s. Per index task, Haiku took 209.9 snow 188.4 s against Luna's 163.5 snow 176.3 s at high, 295.4 snow 288.7 s against 247.3 snow 246.5 s at xhigh, and 424.8 snow 428.7 s against 433.8 snow 421.0 s at max. So on the index tasks it takes about as long as Luna, or longer, at the same setting.

Update, 17 October: Artificial Analysis has re-measured speed since our read, and each new value is shown beside the old one above. Haiku is still the faster writer at every setting it measured for both, and now takes longer than Luna per index task at all three settings. Every score, cost and price in the video is unchanged.

Speed, as re-measured on 17 October

Artificial Analysis's current figures, every setting

output speed, tokens per secondtime to first tokentime per index task
Haiku 5.5 at low177.37.0 s62.5 s
Haiku 5.5 at medium179.09.8 s116.7 s
Haiku 5.5 at high178.515.9 s188.4 s
Haiku 5.5 at xhigh190.240.7 s288.7 s
Haiku 5.5 at max243.1266.6 s428.7 s
GPT-6 Luna at low115.52.8 s–
GPT-6 Luna at medium–––
GPT-6 Luna at high127.115.7 s176.3 s
GPT-6 Luna at xhigh119.625.9 s246.5 s
GPT-6 Luna at max132.3116.2 s421.0 s
Artificial Analysis, read 17 October 2026. These are rolling measurements and change between reads. Artificial Analysis publishes no speed figure for GPT-6 Luna at medium and no time per task for it at low.

The 100,000-token step▶ 7:41

Below 100K tokens, the two price lists match on input and output. Once a Haiku prompt goes over 100K tokens, including any part read from the cache of earlier requests, the whole request costs 5× as much: $0.50 per million input tokens and $2.50 out. GPT-6 Luna's price doesn't move until 272K input tokens. Then, also for the whole request, input costs 2× and output 1.5× as much, $0.20 in and $0.75 out.

So between the two lines Haiku costs 5× as much per token, and past the second line 2.5× as much for input and 3.3× for output.

The prompts that cross the line are long documents, big codebases and long agent runs, where everything so far is sent again with each step. Our max-effort painting crossed it. Priced entirely at the lower rates, its own token counts come to $0.195, already 4.8× the medium run, because it used more tokens. Crossing the line partway through multiplied that by 3.9×, so at list price it cost 19× as much as the medium run. The factor is below 5× because some of the run's requests stayed under the line.

Our max-effort painting, priced below and above the line

Haiku 5.5, one run each, 10 October 2026

costagainst the medium run
medium, at list price$0.0408
max, every token priced at the rates up to 100K$0.1954.8×
max, at list price$0.765719×
Ours: Claude Code's own list-price figures, and our arithmetic on the max run's usage line (102 uncached input, 199,725 one-hour cache-write, 7,357,555 cache-read and 162,994 output tokens) at $0.10, $0.20, $0.01 and $0.50 per million. List price against the below-the-line figure: 3.9×.

If you pay with a Claude plan▶ 8:47

If you use Claude through a Pro or Max plan, the usage limit matters more than the price per token. Anthropic's Claude Academy says "Haiku is the lightest, Sonnet is moderate, Opus is heavy", without giving numbers. OpenAI at least publishes estimates for Codex: on Plus, 350 to 3,000 local messages with GPT-6 Luna every five hours, for Codex running on your own computer.

For Haiku 5.5, a few people have checked their usage bars themselves. Tony Stevenson, on his blog Rambling Rows, ran the same 7 programming jobs on Sonnet 5.5 and Haiku 5.5 on a Pro plan. A run on Sonnet used 6 or 7 points of the five-hour meter. He ran Haiku 8 times in a row and the meter went from 22% to 30%, about one point a run. He calls that a ceiling: the meter shows whole points, and his own session drew on the same limit.

まっちゃん投資ラボ, writing on note.com on a Max 5x plan, got 1 point for Haiku 5.5 on one task at max effort, against 6 for Sonnet 5.5 and 7 for Opus 5.5, one run each. The Sonnet and Opus readings include about one point used by a judge model.

AI Dive, in a post on DEV, ran 140 small Haiku 5.5 tasks (70 at low and 70 at medium) without moving the five-hour bar off 21%. 21 Opus 5.5 tasks moved it from 22% to 23%.

Published readings of the Claude usage meter

Each writer's own measurement

whoplanwhat they ranwhat the meter did
Tony Stevenson, Rambling Rows, 8 OctoberProthe same 7 programming jobs, Sonnet 5.5 and Haiku 5.5Sonnet: 6 or 7 points a run; Haiku: 8 runs moved it from 22% to 30%
まっちゃん投資ラボ, note.com, 8 OctoberMax 5xone task at max effort, one run per modelHaiku 5.5: 1 point; Sonnet 5.5: 6; Opus 5.5: 7 (these two include about one point of a judge model)
AI Dive, DEV, 12 Octobernot stated140 small Haiku 5.5 tasks, then 21 Opus 5.5 tasksHaiku: stayed at 21%; Opus: 22% to 23%
tksfjt1024, Zenn, 1 OctoberMax 20xHaiku 4.5 against Opus 5.5, Septemberper input token, Opus weighs 2.2 times Haiku 4.5 on the limit, against 4 times on the price list
The meter shows whole points. Read 15 October 2026 and re-read 17 October, unchanged; no new Haiku 5.5 reading was published in between that we could find. OpenAI's estimate for Codex on Plus with GPT-6 Luna: 350 to 3,000 local messages per five hours.

Haiku is light on your limit, then, but nobody has measured exactly how light. And the price list is no guide to it. The one precise measurement we found, by tksfjt1024 on Zenn, was of the older Haiku 4.5 in September, on one Max 20x account. Per input token, the limit counted Haiku 4.5 at about half the weight of Opus 5.5 (2.2 to one, Opus to Haiku), even though Haiku 4.5's input price was a quarter of Opus's (4 to one).

To have Claude Code hand its small jobs to Haiku, set the model in the agent's file (model: haiku) or with environment variables (CLAUDE_CODE_SUBAGENT_MODEL=haiku, plus CLAUDE_CODE_SUBAGENT_MODEL_FORCE=1 to apply it to every subagent, the built-in Explore and Plan ones included), because most subagents run on your main model by default. Some of the most-liked posts about Haiku 5.5 recommend a --subagents flag. That flag doesn't exist. We checked Claude Code 2.1.296 when we made the video, and on 17 October the newest release, 2.1.302, still had no such flag.

Which one for what▶ 10:38

For general work at a fixed budget, the Intelligence Index says they're about level. For coding agents paid per token, Luna in Codex: about the same score as Haiku in Claude Code for under a third of the price, and well ahead on software engineering tasks. For agents that mostly work at a command line, for computer use going by Anthropic's own numbers, for work where a confident wrong answer costs you, and for the highest index score if you'll pay for it: Haiku. For sorting jobs like our test, and for prompts past 100K tokens: Luna, on the evidence here. And if you pay through a Claude plan, give the small jobs to Haiku. It's clearly light on your limit, even if nobody can say yet by how much.

AI Actions (made by the company behind this channel)▶ 11:23

Sorting came up earlier, and it's what our own app does too. The company behind this channel makes AI Actions, an iPhone app. One of its actions for iOS Shortcuts is called Choose Category, and it runs on Jev, a model from TypeSafe. It sorts a piece of text, like a reminder about an invoice, into categories you set. You choose how sure it has to be, and when it isn't sure enough about any category, it says it's unsure instead of guessing. It's linked in the video's description.

There'll probably be another new model next week, and we'll measure that one too. If you've used Haiku 5.5 or GPT-6 Luna on real work, tell us in the comments under the video what you ran and which one you kept.

Every number

These are all 411 figures behind the video and this page, grouped by whose they are, with the page each came from and when we read it. Figures marked ⟳ can move. When a re-read finds a change, the new value shows next to the one from the video.

Artificial Analysis, Haiku 5.5 and GPT-6 Luna at every setting (as the video shows them)

Artificial Analysis · Artificial Analysis, Haiku 5.5 release page and data API (every effort setting of Haiku 5.5 and GPT-6 Luna), as the video shows them · read 15 Oct 2026, 14:17 CEST · ⟳ re-read 17 Oct 2026, 07:17 CEST, unchanged · Intelligence Index v4.3.2. Cost per task at API list prices; tokens as each model's API provider counts them. Speeds and times are AA's rolling measurements. · GPT-6 Luna at low has no row on the release page: its score and cost per task in this grid are from Artificial Analysis's full model list, read 8 Oct 2026 (the 'full model list' group below).

Intelligence index score

lowmediumhighxhighmax
Haiku 5.529.534.537.841.243.4
GPT-6 Luna21.529.932.934.638.1

Cost per index task, api list prices

Output tokens over the whole index run

Aa-omniscience, share of questions answered right

lowmediumhighxhighmax
Haiku 5.533.2%34.0%34.8%34.9%36.4%
GPT-6 Luna–43.1%42.8%44.2%43.8%

Aa-omniscience hallucination rate (wrong answers among the questions it didn't get right)

lowmediumhighxhighmax
Haiku 5.544.9%44.8%44.5%44.4%40.4%
GPT-6 Luna–84.7%84.4%82.4%76.7%

Aa-omniscience index (right minus wrong)

lowmediumhighxhighmax
Haiku 5.5+3.25+4.47+5.75+6.05+10.67
GPT-6 Luna–−5.05−5.50−1.83+0.65

Terminal-bench 4.0, share of tasks passed

lowmediumhighxhighmax
Haiku 5.512.6%15.2%21.7%29.3%32.8%
GPT-6 Luna–2.5%4.5%8.1%12.6%

Artificial Analysis, speed and time per task, re-measured 17 October

Output speed, tokens per second, as re-measured 17 oct

lowmediumhighxhighmax
Haiku 5.5177.3179.0178.5190.2243.1
GPT-6 Luna115.5–127.1119.6132.3

Time to first token, as re-measured 17 oct

lowmediumhighxhighmax
Haiku 5.57.0 s9.8 s15.9 s40.7 s266.6 s
GPT-6 Luna2.8 s–15.7 s25.9 s116.2 s

Time per index task, as re-measured 17 oct

lowmediumhighxhighmax
Haiku 5.562.5 s116.7 s188.4 s288.7 s428.7 s
GPT-6 Luna––176.3 s246.5 s421.0 s

Anthropic

Haiku 5.5, price per million input tokens, prompts up to 100K tokens$0.10
Haiku 5.5, price per million cache-read tokens, prompts up to 100K tokens$0.01
Haiku 5.5, price per million one-hour cache-write tokens, prompts up to 100K tokens$0.20
Haiku 5.5, price per million output tokens, prompts up to 100K tokens$0.50
Haiku 5.5, price per million input tokens, prompts over 100K tokens$0.50
Haiku 5.5, price per million cache-read tokens, prompts over 100K tokens$0.05
Haiku 5.5, price per million output tokens, prompts over 100K tokens$2.50
Haiku 5.5, prompt size where the higher price starts, tokens100K
Haiku 4.5, price per million input tokens$1
Haiku 4.5, price per million output tokens$5
Haiku 5.5's price over the 100K line against below it (our arithmetic)5×
Haiku 5.5's price per token as a share of Haiku 4.5's (our arithmetic)10%
Between 100K and 272K tokens: Haiku 5.5's price per token against GPT-6 Luna's (our arithmetic)5×
Past 272K tokens, input: Haiku 5.5's price against GPT-6 Luna's (our arithmetic)2.5×
Past 272K tokens, output: Haiku 5.5's price against GPT-6 Luna's (our arithmetic)3.3×

OpenAI

OpenAI, API pricing (gpt-6-luna) · read 15 Oct 2026, 09:18 CEST
GPT-6 Luna, price per million input tokens, prompts up to 272K tokens$0.10
GPT-6 Luna, price per million cached input tokens, prompts up to 272K tokens$0.01
GPT-6 Luna, price per million output tokens, prompts up to 272K tokens$0.50
GPT-6 Luna, price per million input tokens, prompts over 272K tokens$0.20
GPT-6 Luna, price per million output tokens, prompts over 272K tokens$0.75

OpenAI

GPT-6 Luna, prompt size where the long-prompt price starts, input tokens272K
GPT-6 Luna, long prompts: multiplier on input and cache rates2×
GPT-6 Luna, long prompts: multiplier on the output rate1.5×
GPT-6 Luna's context window, tokens1,050,000

Anthropic

Haiku 5.5's context window, tokens1,000,000

Anthropic

Anthropic: Haiku 5.5's average saving against Haiku 4.575%
Anthropic: Haiku 5.5's price cut against Haiku 4.5, requests up to 100K tokens90%
Anthropic: Haiku 5.5's price cut against Haiku 4.5, requests over 100K tokens50%
Anthropic: share of Haiku 4.5's requests that were up to 100K tokens90%
OSWorld 2.1 offline subset, partial credit, Haiku 5.5 at max (Anthropic's run)72.4%
OSWorld 2.1 offline subset, partial credit, GPT-6 Luna at max (Anthropic's run)48.9%

Anthropic

Anthropic: how many more tokens the new tokenizer counts for the same text30%

Artificial Analysis

input tokens over the whole index run, Haiku 5.5 at medium (release page)1635.72M
cost per index task spent on input, Haiku 5.5 at medium (release page)$0.0306
input tokens over the whole index run, Haiku 5.5 at max (release page)7733.95M
cost per index task spent on input, Haiku 5.5 at max (release page)$0.1317
input tokens over the whole index run, GPT-6 Luna at medium (release page)847.46M
cost per index task spent on input, GPT-6 Luna at medium (release page)$0.0117
input tokens over the whole index run, GPT-6 Luna at max (release page)3146.39M
cost per index task spent on input, GPT-6 Luna at max (release page)$0.0428
Terminal-Bench 4.0, GPT-6 Luna at low (AA's data API)0.0%
Haiku 4.5 (reasoning), Intelligence Index score16.9
output speed at max, Haiku 5.5, tokens per second, as the video shows it240now 243 ⟳
time to first token at max, Haiku 5.5, as the video shows it237 snow 267 s ⟳
time per index task at high, Haiku 5.5, as the video shows it209.9 snow 188.4 s ⟳
time per index task at xhigh, Haiku 5.5, as the video shows it295.4 snow 288.7 s ⟳
time per index task at max, Haiku 5.5, as the video shows it424.8 snow 428.7 s ⟳
output speed at max, GPT-6 Luna, tokens per second, as the video shows it128now 132 ⟳
time to first token at max, GPT-6 Luna, as the video shows it90 snow 116 s ⟳
time per index task at high, GPT-6 Luna, as the video shows it163.5 snow 176.3 s ⟳
time per index task at xhigh, GPT-6 Luna, as the video shows it247.3 snow 246.5 s ⟳
time per index task at max, GPT-6 Luna, as the video shows it433.8 snow 421.0 s ⟳
share of the cost per index task spent on input, Haiku 5.5 at medium (our arithmetic)65%
share of the cost per index task spent on input, Haiku 5.5 at max (our arithmetic)62%
share of the cost per index task spent on input, GPT-6 Luna at medium (our arithmetic)67%
share of the cost per index task spent on input, GPT-6 Luna at max (our arithmetic)63%
input tokens over the index run at medium, Haiku 5.5 against GPT-6 Luna (our arithmetic)1.9×
share of the cost-per-task gap at medium that is input (our arithmetic)64%
input tokens over the index run at max, Haiku 5.5 against GPT-6 Luna (our arithmetic)2.5×
share of the cost-per-task gap at max that is input (our arithmetic)61%
cost per index task at low, Haiku 5.5 against GPT-6 Luna (our arithmetic)5.4×
cost per index task at medium, Haiku 5.5 against GPT-6 Luna (our arithmetic)2.7×
cost per index task at high, Haiku 5.5 against GPT-6 Luna (our arithmetic)2.7×
cost per index task at xhigh, Haiku 5.5 against GPT-6 Luna (our arithmetic)2.9×
cost per index task at max, Haiku 5.5 against GPT-6 Luna (our arithmetic)3.1×
cost per index task, Haiku 5.5 at medium, three decimals (our arithmetic)$0.047
cost per index task, GPT-6 Luna at medium, three decimals (our arithmetic)$0.017
cost per index task, Haiku 5.5 at high, three decimals (our arithmetic)$0.079
cost per index task, GPT-6 Luna at high, three decimals (our arithmetic)$0.029
cost per index task, Haiku 5.5 at xhigh, three decimals (our arithmetic)$0.124
cost per index task, GPT-6 Luna at xhigh, three decimals (our arithmetic)$0.042
cost per index task, Haiku 5.5 at max, three decimals (our arithmetic)$0.213
cost per index task, GPT-6 Luna at max, three decimals (our arithmetic)$0.068
cost per index task, Haiku 5.5 at low, three decimals (our arithmetic)$0.024
output tokens over the index run at max, Haiku 5.5 against GPT-6 Luna (our arithmetic)3.0×
output tokens over the index run at medium, Haiku 5.5 against GPT-6 Luna (our arithmetic)1.9×
output tokens over the index run, Haiku 5.5 at medium, in millions (our arithmetic)53.79M
output tokens over the index run, Haiku 5.5 at max, in millions (our arithmetic)435.18M
output tokens over the index run, GPT-6 Luna at medium, in millions (our arithmetic)28.53M
output tokens over the index run, GPT-6 Luna at max, in millions (our arithmetic)144.38M
AA-Omniscience at max, Haiku 5.5: right (our arithmetic)36.4%
AA-Omniscience at max, Haiku 5.5: share of all questions answered wrong (our arithmetic)25.7%
AA-Omniscience at max, Haiku 5.5: share of all questions not answered or only partly answered (our arithmetic)37.9%
AA-Omniscience at max, GPT-6 Luna: right (our arithmetic)43.8%
AA-Omniscience at max, GPT-6 Luna: share of all questions answered wrong (our arithmetic)43.1%
AA-Omniscience at max, GPT-6 Luna: share of all questions not answered or only partly answered (our arithmetic)13.1%

Artificial Analysis

GPT-6 Luna with no reasoning, Intelligence Index score18.5
GPT-6 Luna with no reasoning, cost per index task$0.0113

Artificial Analysis

tests inside the Intelligence Index10

Artificial Analysis

Coding Agents index, Haiku 5.5 at low in Claude Code28.2
Coding Agents board, cost per task, Haiku 5.5 at low in Claude Code$0.143
Coding Agents board, DeepSWE v1.1 (software engineering tasks), Haiku 5.5 at low in Claude Code45.4%
Coding Agents board, SWE-Atlas-QnA (technical questions about a codebase), Haiku 5.5 at low in Claude Code33.1%
Coding Agents board, Terminal-Bench 4.0 inside the agent, Haiku 5.5 at low in Claude Code6.1%
Coding Agents index, Haiku 5.5 at medium in Claude Code33.6
Coding Agents board, cost per task, Haiku 5.5 at medium in Claude Code$0.226
Coding Agents board, DeepSWE v1.1 (software engineering tasks), Haiku 5.5 at medium in Claude Code47.5%
Coding Agents board, SWE-Atlas-QnA (technical questions about a codebase), Haiku 5.5 at medium in Claude Code41.7%
Coding Agents board, Terminal-Bench 4.0 inside the agent, Haiku 5.5 at medium in Claude Code11.6%
Coding Agents index, Haiku 5.5 at high in Claude Code35.1
Coding Agents board, cost per task, Haiku 5.5 at high in Claude Code$0.365
Coding Agents board, DeepSWE v1.1 (software engineering tasks), Haiku 5.5 at high in Claude Code46.3%
Coding Agents board, SWE-Atlas-QnA (technical questions about a codebase), Haiku 5.5 at high in Claude Code46.2%
Coding Agents board, Terminal-Bench 4.0 inside the agent, Haiku 5.5 at high in Claude Code12.6%
Coding Agents index, Haiku 5.5 at xhigh in Claude Code41.4
Coding Agents board, cost per task, Haiku 5.5 at xhigh in Claude Code$0.610
Coding Agents board, DeepSWE v1.1 (software engineering tasks), Haiku 5.5 at xhigh in Claude Code49.0%
Coding Agents board, SWE-Atlas-QnA (technical questions about a codebase), Haiku 5.5 at xhigh in Claude Code51.6%
Coding Agents board, Terminal-Bench 4.0 inside the agent, Haiku 5.5 at xhigh in Claude Code23.7%
Coding Agents index, Haiku 5.5 at max in Claude Code36.5
Coding Agents board, cost per task, Haiku 5.5 at max in Claude Code$2.580
Coding Agents board, DeepSWE v1.1 (software engineering tasks), Haiku 5.5 at max in Claude Code46.0%
Coding Agents board, SWE-Atlas-QnA (technical questions about a codebase), Haiku 5.5 at max in Claude Code33.6%
Coding Agents board, Terminal-Bench 4.0 inside the agent, Haiku 5.5 at max in Claude Code29.8%
Coding Agents index, GPT-6 Luna at max in Codex41.1
Coding Agents board, cost per task, GPT-6 Luna at max in Codex$0.176
Coding Agents board, DeepSWE v1.1 (software engineering tasks), GPT-6 Luna at max in Codex63.7%
Coding Agents board, SWE-Atlas-QnA (technical questions about a codebase), GPT-6 Luna at max in Codex44.4%
Coding Agents board, Terminal-Bench 4.0 inside the agent, GPT-6 Luna at max in Codex15.2%
Coding Agents board, cost per task, Haiku 5.5 at xhigh in Claude Code, to the cent (our arithmetic)$0.61
Coding Agents board, cost per task, GPT-6 Luna at max in Codex, to the cent (our arithmetic)$0.18
Coding Agents board, cost per task, Haiku 5.5 at max in Claude Code, to the cent (our arithmetic)$2.58
Coding Agents board, GPT-6 Luna at max's cost per task against Haiku 5.5 at xhigh's (our arithmetic)0.29×
Terminal-Bench 4.0, Coding Agents board, Haiku 5.5 at xhigh in Claude Code, as a share (our arithmetic)23.7%
Terminal-Bench 4.0, Coding Agents board, Haiku 5.5 at max in Claude Code, as a share (our arithmetic)29.8%
Terminal-Bench 4.0, Coding Agents board, GPT-6 Luna at max in Codex, as a share (our arithmetic)15.2%

Vals

Vals, Vals Index, Claude Haiku 5.554.44%
Vals, Vals Index, Claude Haiku 5.5, Vals's ± interval±1.41
Vals, Vals Index, GPT-6 Luna at max51.22%
Vals, Vals Index, GPT-6 Luna at max, Vals's ± interval±1.07
Vals, Code Migration, Claude Haiku 5.544.57%
Vals, Code Migration, Claude Haiku 5.5, Vals's ± interval±4.23
Vals, Code Migration, GPT-6 Luna at max42.55%
Vals, Code Migration, GPT-6 Luna at max, Vals's ± interval±4.42
Vals, CyberBench v1.1, Claude Haiku 5.575.48%
Vals, CyberBench v1.1, Claude Haiku 5.5, Vals's ± interval±5.21
Vals, CyberBench v1.1, GPT-6 Luna at max76.25%
Vals, CyberBench v1.1, GPT-6 Luna at max, Vals's ± interval±5.29
Vals, EMB, Claude Haiku 5.559.02%
Vals, EMB, Claude Haiku 5.5, Vals's ± interval±4.17
Vals, EMB, GPT-6 Luna at max68.52%
Vals, EMB, GPT-6 Luna at max, Vals's ± interval±2.81
Vals, Finance Agent (v2), Claude Haiku 5.554.14%
Vals, Finance Agent (v2), Claude Haiku 5.5, Vals's ± interval±2.13
Vals, Finance Agent (v2), GPT-6 Luna at max49.87%
Vals, Finance Agent (v2), GPT-6 Luna at max, Vals's ± interval±0.23
Vals, MedCode, Claude Haiku 5.551.54%
Vals, MedCode, Claude Haiku 5.5, Vals's ± interval±2.17
Vals, MedCode, GPT-6 Luna at max44.69%
Vals, MedCode, GPT-6 Luna at max, Vals's ± interval±2.30
Vals, MedScribe, Claude Haiku 5.589.54%
Vals, MedScribe, Claude Haiku 5.5, Vals's ± interval±1.92
Vals, MedScribe, GPT-6 Luna at max83.71%
Vals, MedScribe, GPT-6 Luna at max, Vals's ± interval±1.95
Vals, MysteryMechanism, Claude Haiku 5.535.13%
Vals, MysteryMechanism, Claude Haiku 5.5, Vals's ± interval±3.21
Vals, MysteryMechanism, GPT-6 Luna at max19.37%
Vals, MysteryMechanism, GPT-6 Luna at max, Vals's ± interval±2.66
Vals, ProofBench v1.1, Claude Haiku 5.589.00%
Vals, ProofBench v1.1, Claude Haiku 5.5, Vals's ± interval±3.15
Vals, ProofBench v1.1, GPT-6 Luna at max64.00%
Vals, ProofBench v1.1, GPT-6 Luna at max, Vals's ± interval±4.82
Vals, SAGE, Claude Haiku 5.545.78%
Vals, SAGE, Claude Haiku 5.5, Vals's ± interval±3.42
Vals, SAGE, GPT-6 Luna at max48.09%
Vals, SAGE, GPT-6 Luna at max, Vals's ± interval±3.38
Vals, Public Benefits Bench v1.1, Claude Haiku 5.563.19%
Vals, Public Benefits Bench v1.1, Claude Haiku 5.5, Vals's ± interval±1.25
Vals, Public Benefits Bench v1.1, GPT-6 Luna at max57.65%
Vals, Public Benefits Bench v1.1, GPT-6 Luna at max, Vals's ± interval±1.28
Vals, SRE Bench, Claude Haiku 5.55.72%
Vals, SRE Bench, Claude Haiku 5.5, Vals's ± interval±1.44
Vals, SRE Bench, GPT-6 Luna at max2.67%
Vals, SRE Bench, GPT-6 Luna at max, Vals's ± interval±1.00
Vals, Tax Agent Bench, Claude Haiku 5.531.92%
Vals, Tax Agent Bench, Claude Haiku 5.5, Vals's ± interval±3.35
Vals, Tax Agent Bench, GPT-6 Luna at max19.95%
Vals, Tax Agent Bench, GPT-6 Luna at max, Vals's ± interval±2.87
Vals, Vibe Code Bench 1-100, Claude Haiku 5.520.41%
Vals, Vibe Code Bench 1-100, Claude Haiku 5.5, Vals's ± interval±3.79
Vals, Vibe Code Bench v1.1, Claude Haiku 5.590.44%
Vals, Vibe Code Bench v1.1, Claude Haiku 5.5, Vals's ± interval±1.73
Vals, Vibe Code Bench v1.1, GPT-6 Luna at max81.65%
Vals, Vibe Code Bench v1.1, GPT-6 Luna at max, Vals's ± interval±3.38
Vals, BioMysteryBench, Claude Haiku 5.570.37%
Vals, BioMysteryBench, Claude Haiku 5.5, Vals's ± interval±1.33
Vals, BioMysteryBench, GPT-6 Luna at max61.48%
Vals, BioMysteryBench, GPT-6 Luna at max, Vals's ± interval±2.59
Vals, Harvey's Legal Agent Benchmark, Claude Haiku 5.51.25%
Vals, Harvey's Legal Agent Benchmark, Claude Haiku 5.5, Vals's ± interval±0.72
Vals, Harvey's Legal Agent Benchmark, GPT-6 Luna at max2.92%
Vals, Harvey's Legal Agent Benchmark, GPT-6 Luna at max, Vals's ± interval±1.36
Vals, IOI, Claude Haiku 5.547.28%
Vals, IOI, Claude Haiku 5.5, Vals's ± interval±10.72
Vals, IOI, GPT-6 Luna at max55.56%
Vals, IOI, GPT-6 Luna at max, Vals's ± interval±8.87
Vals, ProgramBench, Claude Haiku 5.52.50%
Vals, ProgramBench, Claude Haiku 5.5, Vals's ± interval±1.11
Vals, ProgramBench, GPT-6 Luna at max0.50%
Vals, ProgramBench, GPT-6 Luna at max, Vals's ± interval±0.50
Vals, SWE-bench Multimodal, Claude Haiku 5.543.96%
Vals, SWE-bench Multimodal, Claude Haiku 5.5, Vals's ± interval±2.27
Vals, SWE-bench Multimodal, GPT-6 Luna at max37.50%
Vals, SWE-bench Multimodal, GPT-6 Luna at max, Vals's ± interval±2.21
Vals, Terminal-Bench 4.0, Claude Haiku 5.536.36%
Vals, Terminal-Bench 4.0, Claude Haiku 5.5, Vals's ± interval±2.31
Vals, Terminal-Bench 4.0, GPT-6 Luna at max13.64%
Vals, Terminal-Bench 4.0, GPT-6 Luna at max, Vals's ± interval±1.51
Vals, Terminal-Bench Science, Claude Haiku 5.510.00%
Vals, Terminal-Bench Science, Claude Haiku 5.5, Vals's ± interval±3.61
Vals, Terminal-Bench Science, GPT-6 Luna at max4.29%
Vals, Terminal-Bench Science, GPT-6 Luna at max, Vals's ± interval±2.44
Terminal-Bench 4.0, Vals, Haiku 5.5, as a share (our arithmetic)36.4%
Terminal-Bench 4.0, Vals, GPT-6 Luna at max, as a share (our arithmetic)13.6%

Vals

Vals, Vals Science Index (added by 17 Oct), Claude Haiku 5.538.50%
Vals, Vals Science Index (added by 17 Oct), GPT-6 Luna at max28.38%
Vals Science Index (added by 17 Oct), Claude Haiku 5.5, Vals's ± interval±1.67
Vals Science Index (added by 17 Oct), GPT-6 Luna, Vals's ± interval±1.48

Vals

the effort setting Vals ran Claude Haiku 5.5 atmax
Vals, cost per test on the Vals Index, Claude Haiku 5.5$3.000

Vals

Vals, GPT-6 Luna model page (cost per test) · read 15 Oct 2026, 09:18 CEST
Vals, cost per test on the Vals Index, GPT-6 Luna$0.431

Anthropic

Anthropic, Claude Haiku 5.5 system card · read 8 Oct 2026, 10:10 CEST
OSWorld 2.1 offline subset, Haiku 5.5's strict pass rate37.1%
tasks in the OSWorld subset Anthropic ran both models on82

Model Fatigue (our runs)

Our Great Wave runs (Claude Code and Codex, one run each) · run 10 Oct 2026 (Sonnet 5.5 and Opus 5.5: 28 Sep 2026)
our Great Wave run, Haiku 4.5 in Claude Code at its default: agent time379 s
our Great Wave run, Haiku 4.5 in Claude Code at its default: Claude Code's list-price cost$0.33
our Great Wave run, Haiku 5.5 at medium: agent time329 s
our Great Wave run, Haiku 5.5 at medium: Claude Code's list-price cost$0.04
our Great Wave run, Haiku 5.5 at max: agent time859 s
our Great Wave run, Haiku 5.5 at max: Claude Code's list-price cost$0.77
our Great Wave run, GPT-6 Luna in Codex at max: agent time317 s
our Great Wave run, Sonnet 5.5 at its default (28 Sep): agent time98 s
our Great Wave run, Sonnet 5.5 at its default (28 Sep): Claude Code's list-price cost$0.21
our Great Wave run, Opus 5.5 at its default (28 Sep): agent time327 s
our Great Wave run, Opus 5.5 at its default (28 Sep): Claude Code's list-price cost$1.03

Model Fatigue, arithmetic on our run

Our two Haiku 5.5 painting runs' result lines: Claude Code's list-price totals for the medium and max runs, the max run's token counts, and our arithmetic on them (derived/painting.json) · run 10 Oct 2026, 07:47 CEST
our max run, priced at the rates below the 100K line$0.195
our medium run, Claude Code's list-price cost to the hundredth of a cent$0.0408
our max run, Claude Code's list-price cost to the hundredth of a cent$0.7657
our max run, cache-read tokens7,357,555
our max run, one-hour cache-write tokens199,725
our max run, output tokens162,994
our max run, uncached input tokens102
our max run below the line against the medium run (our arithmetic)4.8×
our max run at list price against the same run priced below the line (our arithmetic)3.9×
our max run against the medium run, list price (our arithmetic)19×

The Metropolitan Museum of Art

when the print was first publishedc. 1830–32

Model Fatigue (our test)

Our contact-form test: 610 messages from a tutoring business's website form, one run per setting · run 8 Oct 2026
our contact-form test, Haiku 5.5 at low: share of messages agreeing with the labels79.2%
our contact-form test, Haiku 5.5 at low: messages agreeing with the labels483
our contact-form test, Haiku 5.5 at low: messages labelled spam that it let through119
our contact-form test, Haiku 5.5 at low: messages labelled genuine that it marked as spam8
our contact-form test, Haiku 5.5 at low: cost per 1,000 messages at list price$0.135
our contact-form test, Haiku 5.5 at low: input tokens per message, average775
our contact-form test, Haiku 5.5 at low: output tokens per message, average115
our contact-form test, Haiku 5.5 at low: median time per message1.53 s
our contact-form test, Haiku 5.5 at medium: share of messages agreeing with the labels82.0%
our contact-form test, Haiku 5.5 at medium: messages agreeing with the labels500
our contact-form test, Haiku 5.5 at medium: messages labelled spam that it let through103
our contact-form test, Haiku 5.5 at medium: messages labelled genuine that it marked as spam7
our contact-form test, Haiku 5.5 at medium: cost per 1,000 messages at list price$0.176
our contact-form test, Haiku 5.5 at medium: input tokens per message, average775
our contact-form test, Haiku 5.5 at medium: output tokens per message, average198
our contact-form test, Haiku 5.5 at medium: median time per message1.70 s
our contact-form test, GPT-6 Luna at low: share of messages agreeing with the labels88.9%
our contact-form test, GPT-6 Luna at low: messages agreeing with the labels542
our contact-form test, GPT-6 Luna at low: messages labelled spam that it let through57
our contact-form test, GPT-6 Luna at low: messages labelled genuine that it marked as spam11
our contact-form test, GPT-6 Luna at low: cost per 1,000 messages at list price$0.081
our contact-form test, GPT-6 Luna at low: input tokens per message, average409
our contact-form test, GPT-6 Luna at low: output tokens per message, average81
our contact-form test, GPT-6 Luna at low: median time per message2.30 s
our contact-form test, GPT-6 Luna at medium: share of messages agreeing with the labels88.4%
our contact-form test, GPT-6 Luna at medium: messages agreeing with the labels539
our contact-form test, GPT-6 Luna at medium: messages labelled spam that it let through60
our contact-form test, GPT-6 Luna at medium: messages labelled genuine that it marked as spam11
our contact-form test, GPT-6 Luna at medium: cost per 1,000 messages at list price$0.106
our contact-form test, GPT-6 Luna at medium: input tokens per message, average409
our contact-form test, GPT-6 Luna at medium: output tokens per message, average131
our contact-form test, GPT-6 Luna at medium: median time per message2.82 s
our contact-form test: messages610
our contact-form test: messages the keyword rules label genuine128
our contact-form test: messages the keyword rules label spam482
our contact-form test, GPT-6 Luna at low minus Haiku 5.5 at medium: paired difference in agreement, points+6.9
our contact-form test, GPT-6 Luna at low minus Haiku 5.5 at medium: 95% interval, low+4.4
our contact-form test, GPT-6 Luna at low minus Haiku 5.5 at medium: 95% interval, high+9.3
our contact-form test, Haiku 5.5 at low minus Haiku 5.5 at medium: paired difference in agreement, points−2.8
our contact-form test, Haiku 5.5 at low minus Haiku 5.5 at medium: 95% interval, low−5.1
our contact-form test, Haiku 5.5 at low minus Haiku 5.5 at medium: 95% interval, high−0.7
our contact-form test, GPT-6 Luna at low minus GPT-6 Luna at medium: paired difference in agreement, points+0.5
our contact-form test, GPT-6 Luna at low minus GPT-6 Luna at medium: 95% interval, low−0.7
our contact-form test, GPT-6 Luna at low minus GPT-6 Luna at medium: 95% interval, high+1.6
spam let through, Haiku 5.5 at medium against GPT-6 Luna at low (our arithmetic)1.8×

Model Fatigue (our test)

Where our contact-form test's messages and labels come from (a census of the business's website-form submissions, 5 Sep 2026, and the eval's system prompt) · copied 17 Oct 2026, from the-study-pro at commit 994e96c (8 Sep 2026)
the census: messages labelled likely spam by the keyword rules482
the census: messages labelled real128
messages scored (staff and unsure rows dropped)610

OpenAI

OpenAI's estimate of local Codex messages per 5 hours on Plus with GPT-6 Luna, low end350
OpenAI's estimate of local Codex messages per 5 hours on Plus with GPT-6 Luna, high end3,000

Tony Stevenson

Stevenson: Sonnet 5.5's use of the 5-hour meter per run of his suite, low end (points)6
Stevenson: Sonnet 5.5's use of the 5-hour meter per run, high end (points)7
Stevenson: the 5-hour meter before eight Haiku 5.5 runs22%
Stevenson: the 5-hour meter after them30%
Stevenson: Haiku 5.5 runs of his suite8
Stevenson: programming jobs in his suite7

まっちゃん投資ラボ

まっちゃん投資ラボ: Haiku 5.5's use of the 5-hour limit on one task, points1
まっちゃん投資ラボ: Sonnet 5.5's, points6
まっちゃん投資ラボ: Opus 5.5's, points7

AI Dive

AI Dive: Haiku 5.5 tasks at low70
AI Dive: Haiku 5.5 tasks at medium70
AI Dive: the 5-hour meter before and after the Haiku 5.5 tasks21%
AI Dive: Opus 5.5 tasks21
AI Dive: the meter before the Opus 5.5 tasks22%
AI Dive: the meter after them23%
AI Dive: Haiku 5.5 tasks in all (our arithmetic)140

tksfjt1024

tksfjt1024: Opus 5.5's weight on the 5-hour limit per input token, Haiku 4.5 = 12.2
tksfjt1024: Opus 5.5's API input price, Haiku 4.5 = 14

Anthropic

Claude Code docs, Create custom subagents · read 15 Oct 2026, 06:17 CEST
the variable that applies the subagent model to every subagent, built-in ones includedCLAUDE_CODE_SUBAGENT_MODEL_FORCE=1

Model Fatigue

Our check of the Claude Code binaries for a --subagents flag · checked 17 Oct 2026, 07:19 CEST
the Claude Code version we first checked for a --subagents flag2.1.296
the newest Claude Code release on 17 Oct 2026, also without the flag2.1.302

Sources

These are the pages the video and this page draw on. We keep a copy of each page as we read it, so a figure can be checked against what the page said at the time.

Credits

The narration in the video is an AI voice, made with ElevenLabs.

Music in the video: "Airport Lounge" by Kevin MacLeod (incompetech.com), licensed under Creative Commons: By Attribution 4.0.

Hokusai's Under the Wave off Kanagawa: The Metropolitan Museum of Art, public domain.