This is the video written out, with every figure in full, each linked to its source in the table below.
A new Sol, a week after the last one▶ 0:00
OpenAI released GPT-6 Sol on 22 September. Seven days later, on 29 September, it released GPT-6.1 Sol, which its launch post calls an upgrade to GPT-6 Sol.
OpenAI pitches it against its own top model, GPT-6 Astra, as "near-Astra intelligence for a fifth of the price". For a lot of people, though, the model to compare it with is Anthropic's Opus 5.5. On Artificial Analysis's Intelligence Index, an independent score averaged over ten tests, the two score about the same at their lowest effort setting: 42.1 for Sol and 42.3 for Opus. Sol gets there for $0.13 a task against $0.55 for Opus, which is 0.24 of the cost, about a quarter. So what happens when you turn them both up?
The basics▶ 0:44
GPT-6.1 Sol costs the same per token as GPT-6 Sol for input and output, $2 per million input tokens and $10 per million output tokens, and cached input drops from $0.20 to $0.10 per million. Each of those is half what Opus 5.5 charges.
Price per million tokens
API list prices
You can use it through the API, and in Codex and ChatGPT Work on the Plus, Pro, Business, Enterprise and Edu plans. OpenAI says it isn't yet available in the regular ChatGPT chat. Its context window is 1,050,000 tokens, and it has five effort settings, low, medium, high, xhigh and max, with medium as the API's default.
On Artificial Analysis's main list, which puts each model at its top setting, four models score higher than GPT-6.1 Sol: Opus 5.5, Sonnet 5.5, Fable 5.1 and GPT-6 Astra. Sol costs less per task than any of them. Against the cheapest of the four, Astra at $3.26, Sol's $0.72 is 0.22 of the cost.
The top five on Artificial Analysis's main list
Each model at its top setting
| model | Intelligence Index | cost per task |
|---|---|---|
| Opus 5.5 | 57.6 | $5.98 |
| Sonnet 5.5 | 56.0 | $7.60 |
| Fable 5.1 | 53.4 | $7.63 |
| GPT-6 Astra | 52.7 | $3.26 |
| GPT-6.1 Sol | 51.8 | $0.72 |
If you use GPT-6 Sol, this is the one to try first. At every setting it scores four to eight points higher, from +4.3 points at max to +8.2 points at low, for the same money or less.
GPT-6.1 Sol against GPT-6 Sol
Intelligence Index score and cost per task at each setting
| setting | GPT-6.1 Sol | GPT-6 Sol | difference | cost, GPT-6.1 Sol against GPT-6 Sol |
|---|---|---|---|---|
| low | 42.1 at $0.13 | 33.9 at $0.13 | +8.2 | 0.99 |
| medium | 47.8 at $0.21 | 39.8 at $0.25 | +8.0 | 0.86 |
| high | 50.2 at $0.32 | 42.8 at $0.38 | +7.4 | 0.85 |
| xhigh | 51.0 at $0.39 | 44.1 at $0.52 | +6.9 | 0.75 |
| max | 51.8 at $0.72 | 47.5 at $1.05 | +4.3 | 0.69 |
Every setting against Opus 5.5▶ 1:52
Every setting against Opus 5.5
Intelligence Index score against cost per task, each model at its five effort settings. The yellow lines join the two pairs the text compares.
At low, the two are level. At medium, Opus pulls ahead, 51.2 against 47.8. The closer match is Sol at high against Opus at medium. Sol scores 50.2, 1.0 points lower, and costs $0.32 a task against $1.34, which is 0.24 of the cost.
Part of that gap is the price per token, which is half. The rest is how much each model writes and reads. At that pair, Sol writes 13.2K output tokens per task against 25.7K for Opus, 0.51 as many. It also reads about 541K tokens from cache per task against about 2.05M, 0.26 as many. We worked those two cache figures out from Artificial Analysis's cost split and each model's cache price.
Turn Sol all the way up to max and it edges past Opus at medium, 51.8 against 51.2, for 0.54 of the cost. But that's as high as Sol goes. Opus keeps climbing, to 56.0 at xhigh and 57.6 at max. So a quarter of the price gets you to about Opus at medium, and not beyond it.
For Sol, high is where turning it up stops paying. Going from high to max adds +1.6 points for 2.27× the cost per task.
Sol at high is slower to start answering than Opus at medium. On Artificial Analysis's speed test, Sol at high takes 57.6 snow 58.0 s to its first answer token, against 21.9 snow 23.0 s for Opus at medium. On the index tasks themselves, the two take about the same time on average, 205 snow 206 s and 216 snow 219 s. These speed figures are rolling measurements that move from day to day, so where a re-read found a new value, it's shown next to the one from the video.
Where Sol comes out ahead▶ 3:15
The index combines ten tests, and that hides where the two differ. Split by the kind of work, Sol leads on two kinds at most settings, and Opus leads on most of the rest.
Answering questions from long documents full of tables and fine print is Sol's best case. On GDP.pdf, a document test that Artificial Analysis runs, Sol is ahead of Opus at every setting from medium up. Its best score is 32.0%, at high, against 28.8% for Opus at its best, also at high. OpenAI's launch chart for GDP.pdf shows the same values.
The other is business workflows with tools, on AutomationBench as Artificial Analysis runs it. Sol is slightly ahead at medium, high and xhigh, and only at max does Opus pull ahead, 69.5% against Sol's best of 66.6%, which Sol reached at xhigh.
Artificial Analysis's release page has no test scores for Opus at low, so the table starts at medium. Its Sonnet 5.5 page, read on 29 September, has two: at low, Opus scores 31.3% on Terminal-Bench 4.0 against 30.8% for Sol, and 1224 on GDPval-AA against 1297, so at low Sol leads on GDPval-AA.
By kind of work
Scores on the tests inside the index, GPT-6.1 Sol and Opus 5.5 at each setting from medium up
| test | model | medium | high | xhigh | max |
|---|---|---|---|---|---|
| GDP.pdf (questions over long documents) | GPT-6.1 Sol | 30.0% | 32.0% | 31.8% | 31.0% |
| Opus 5.5 | 25.6% | 28.8% | 26.6% | 26.2% | |
| AutomationBench (business workflows with tools) | GPT-6.1 Sol | 62.6% | 64.5% | 66.6% | 64.9% |
| Opus 5.5 | 61.2% | 63.2% | 65.0% | 69.5% | |
| Terminal-Bench 4.0 (work in a terminal) | GPT-6.1 Sol | 48.0% | 51.5% | 54.0% | 56.1% |
| Opus 5.5 | 52.5% | 56.6% | 59.6% | 59.6% | |
| GDPval-AA, Elo (finished work, judged by an AI judge) | GPT-6.1 Sol | 1433 | 1486 | 1510 | 1575 |
| Opus 5.5 | 1576 | 1692 | 1820 | 1846 | |
| AA-Briefcase, Elo (multi-week agent projects) | GPT-6.1 Sol | 1365 | 1471 | 1507 | 1564 |
| Opus 5.5 | 1642 | 1704 | 1780 | 1822 | |
| Humanity's Last Exam (very hard questions) | GPT-6.1 Sol | 49.9% | 51.4% | 52.6% | 52.9% |
| Opus 5.5 | 54.7% | 55.6% | 57.5% | 61.4% | |
| CritPt (research physics) | GPT-6.1 Sol | 27.7% | 30.0% | 31.7% | 31.7% |
| Opus 5.5 | 27.7% | 30.9% | 31.7% | 31.7% |
Where Opus stays ahead▶ 4:03
Opus leads on most of the other tests. On work in a terminal, Terminal-Bench 4.0, it's ahead at every setting from medium up, 59.6% against 56.1% at max. On GDPval-AA, where an AI judge compares finished work like documents, spreadsheets and slides, Opus is well ahead from medium up (at low, Sol is ahead), and Opus at medium, 1576, already matches the best Sol does, 1575 at max. Opus is also well ahead on AA-Briefcase, Artificial Analysis's test of agent work on multi-week business projects, 1822 against 1564 at max.
On Humanity's Last Exam, a set of very hard questions, Opus at max is 8.4 points ahead of Sol at max. On CritPt, a research physics test, they tie at max, 31.7% each.
At max, test by test
Score on each test inside the index, both models at max
The numbers in this chart
| Opus 5.5 | GPT-6.1 Sol | Sol minus Opus | |
|---|---|---|---|
| GDP.pdf | 26.2% | 31.0% | +4.8 points |
| AutomationBench | 69.5% | 64.9% | −4.7 points |
| Terminal-Bench 4.0 | 59.6% | 56.1% | −3.5 points |
| Humanity's Last Exam | 61.4% | 52.9% | −8.4 points |
| CritPt | 31.7% | 31.7% | 0.0 points |
OpenAI's own launch charts agree at the top. On its Terminal-Bench Science chart, a test of scientific work in a terminal, OpenAI plots Opus at max at 63.3%, higher than GPT-6.1 Sol at any setting. Sol's best there is 57.0%, at max. OpenAI says it took its competitor points from "publicly available reports", and Anthropic's own figure for Opus 5.5 on that test is 58.7%, which is also above Sol's best.
OpenAI's Terminal-Bench Science chart
Score at each setting, from the values embedded in OpenAI's launch post
| low | medium | high | xhigh | max | |
|---|---|---|---|---|---|
| GPT-6.1 Sol | 43.7% | 47.6% | 51.1% | 53.7% | 57.0% |
| Opus 5.5, as OpenAI plotted it | 63.3% | ||||
| Opus 5.5, Anthropic's own figure | 58.7% |
In a coding agent▶ 4:54
One more measurement arrived after launch, on coding agents. Artificial Analysis now runs whole agents, each with its own model, through three sets of coding tasks. Claude Code with Opus 5.5 at max scores 66.0, at $13.04 a task, and takes 64 min on each. Codex with GPT-6.1 Sol at xhigh scores 62.9, at $1.04 a task, 0.08 of the cost or about a twelfth, in 16 min. That also puts it ahead of Codex with GPT-6 Astra at max, 61.6, at 0.14 of Astra's cost.
Opus 5.5 has only been run at max so far, so there's no cheaper Opus setting to set against it yet. The top of the list, for now, is Claude Code with Sonnet 5.5 at max, at 68.4.
Artificial Analysis's Coding Agent Index
Each agent running one model at one setting, on DeepSWE v1.1, SWE-Atlas-QnA and Terminal-Bench v4
| agent and model | index | cost per task | time per task |
|---|---|---|---|
| Claude Code, Sonnet 5.5 at max | 68.4 | $14.19 | 87 min |
| Claude Code, Opus 5.5 at max | 66.0 | $13.04 | 64 min |
| Codex, GPT-6.1 Sol at xhigh | 62.9 | $1.04 | 16 min |
| Claude Code, Fable 5.1 at max | 62.2 | $12.39 | 35 min |
| Codex, GPT-6 Astra at max | 61.6 | $7.47 | 29 min |
| Codex, GPT-6.1 Sol at medium | 61.4 | $0.70 | 11 min |
| Codex, GPT-6.1 Sol at high | 60.1 | $0.89 | 13 min |
| Codex, GPT-6.1 Sol at max | 60.1 | $1.55 | 24 min |
| Codex, GPT-6.1 Sol at low | 57.2 | $0.50 | 9 min |
| Codex, GPT-6 Sol at max | 56.7 | $2.99 | 22 min |
Our test: the Great Wave▶ 5:33
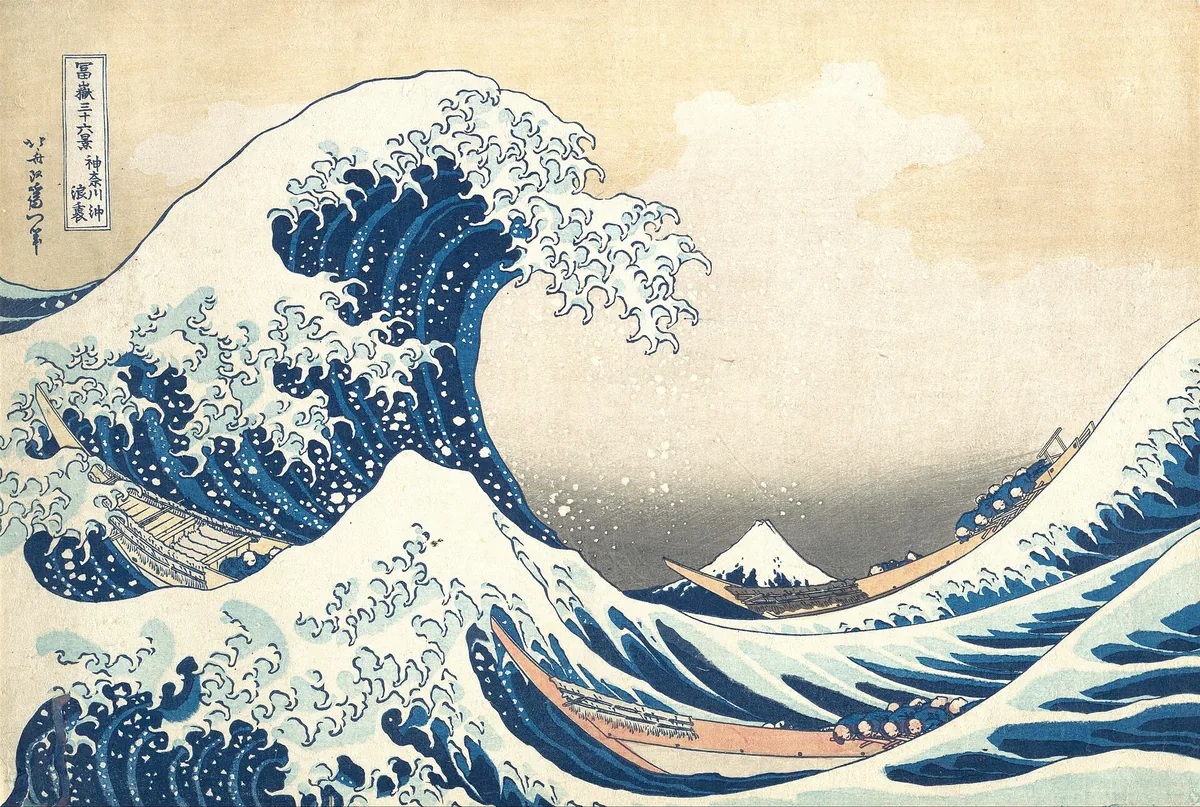
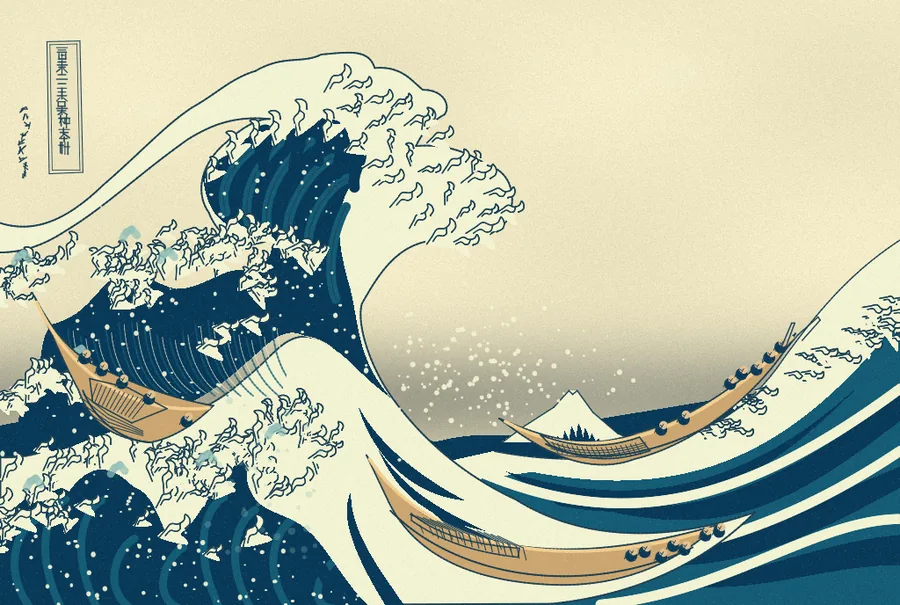
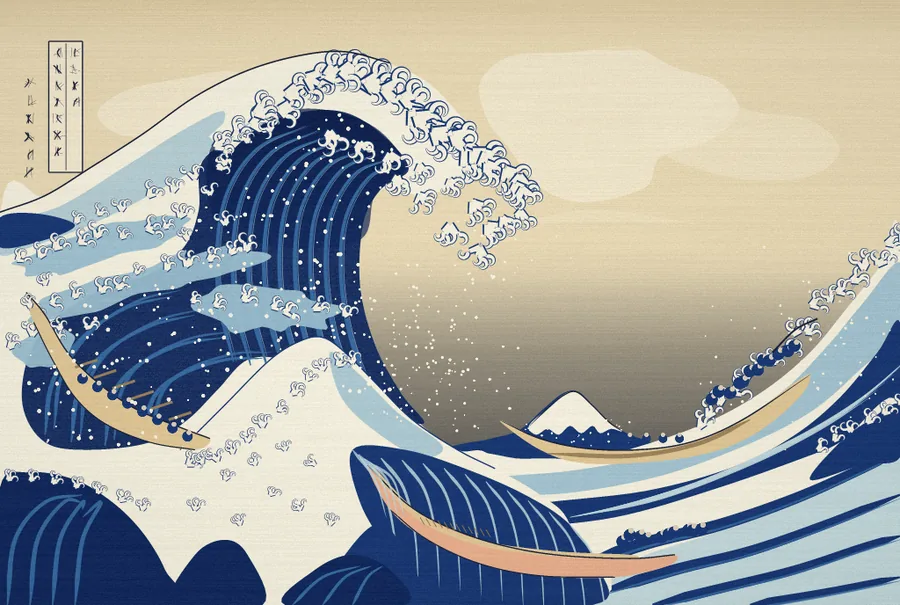
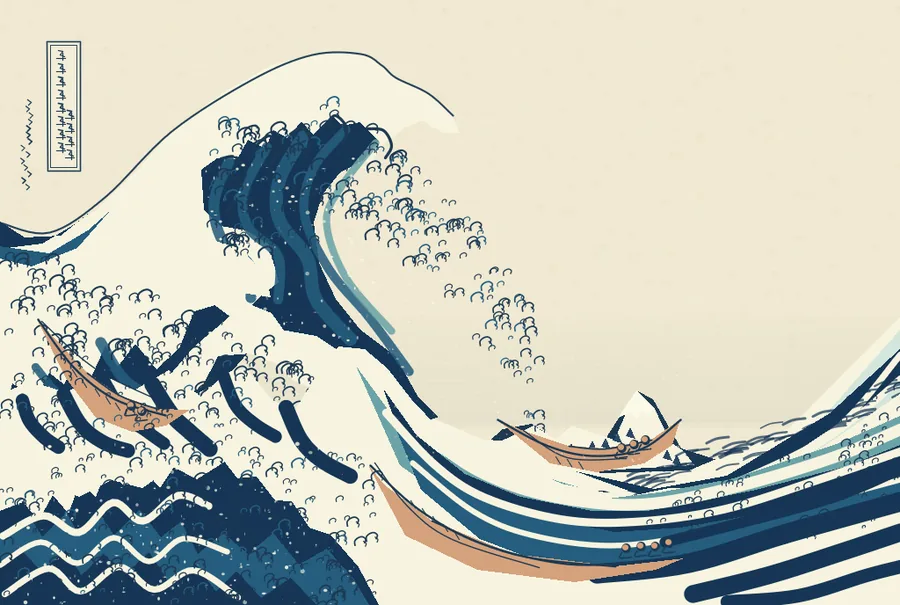
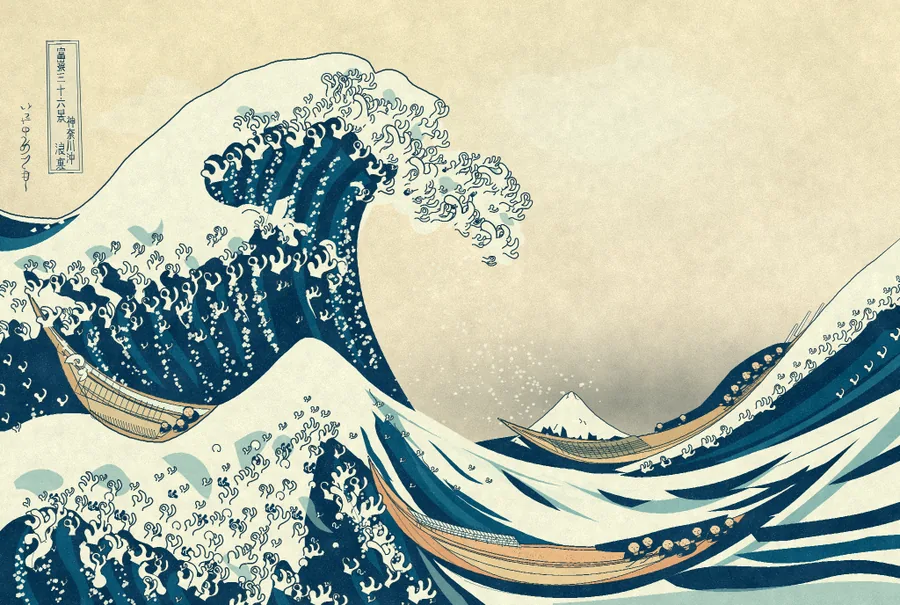
Each model gets the same job: look at Hokusai's Great Wave and paint it by writing its own painting program, with no image model and no image library. We ran it once per model at each tool's default setting, GPT-6.1 Sol, GPT-6 Sol and GPT-6 Astra in Codex, and Opus 5.5 in Claude Code.
Four models, one prompt, the Great Wave
$0.15 at API prices
$1.03 at API prices
$0.25 at API prices
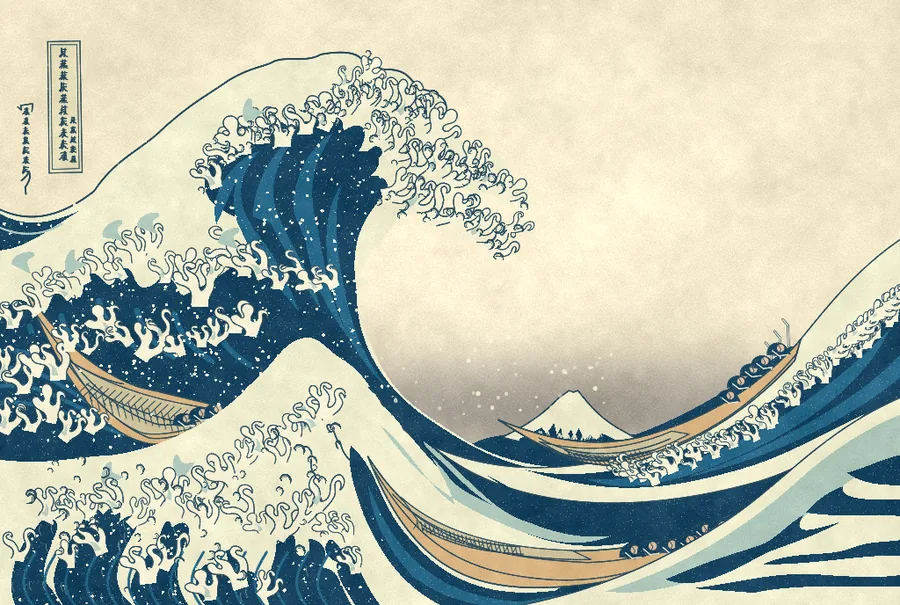
$1.60 at API prices
To our eye, GPT-6.1 Sol's wave has what the print has, the boats, Mount Fuji and the title box, and it's closer to the print than GPT-6 Sol's. Astra's is still the closest. Opus's is more stylized, with its own colours and shapes. Priced at API rates, Sol's painting cost $0.15 and Opus's $1.03, so on this one job Sol cost 0.15 of what Opus did, a smaller share than the quarter on the index.
We also ran Sol's painting at low, high, xhigh and max, as well as the default. The high and max runs took 22 min and 29 min and came to 17.3 and 18.8 Codex credits at the rate card's prices, against 3.8 credits at the default, for a fuller painting closer to the print.
GPT-6.1 Sol's painting at four of its settings
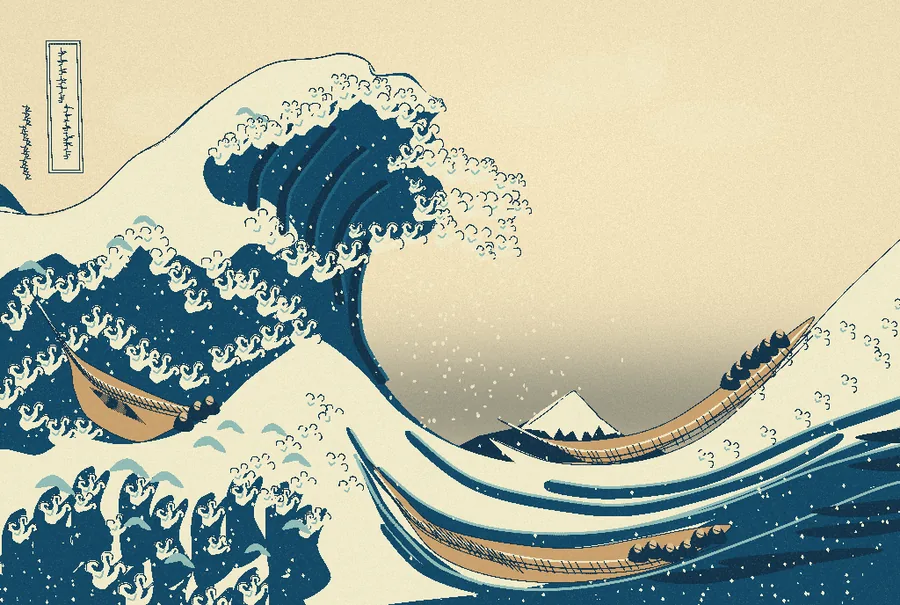
5 min · 3.2 credits
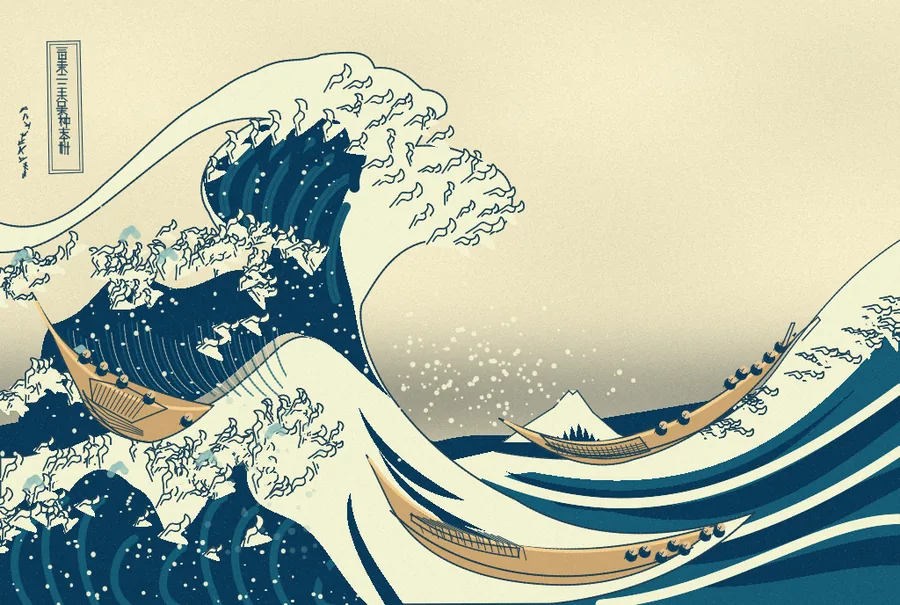
5 min · 3.8 credits
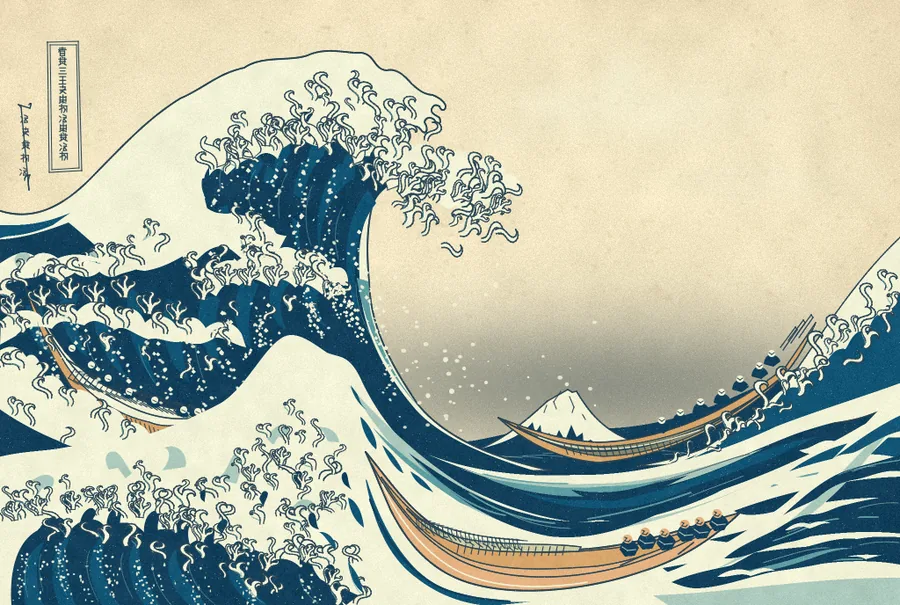
22 min · 17.3 credits
29 min · 18.8 credits
The xhigh painting isn't shown. Its program has more numbers written into it than our test allows, a check that is there to catch a model copying image data. Reading the program, we found hand-placed curves rather than an encoded image, but we kept it out, as the video does.
These are single runs, so they show what each model can do, and nothing about how often it does it.
Against Astra and Fable▶ 6:44
Against GPT-6 Astra, OpenAI's own top model, Sol at high scores 50.2, within a point of Astra at high, 50.9, for 0.18 of the cost per task, about a fifth. At their top settings Astra stays ahead, 52.7 against 51.8.
On OpenAI's credit rate card for Codex, an Astra token costs 5× as many credits as a Sol token, and 10× as many on cached input, which is most of what a coding agent reads. In our GPT-6.1 Sol Great Wave run, for example, Sol read 168,576 tokens from cache and 25,427 fresh ones, and wrote 8,483.
OpenAI's Codex credit rate card
Credits per million tokens, on credit-based plans
Against Anthropic's Fable 5.1, Sol at max, 51.8, matches Fable at high, 51.2, for 0.19 of the cost, about a fifth. Fable at max goes on to 53.4.
Against Astra and Fable
Intelligence Index score against cost per task, four models at their five settings. The yellow lines join the two pairs the text compares.
The numbers in this chart
| setting | GPT-6.1 Sol score | GPT-6.1 Sol cost per index task | GPT-6 Astra score | GPT-6 Astra cost per index task | Opus 5.5 score | Opus 5.5 cost per index task | Fable 5.1 score | Fable 5.1 cost per index task |
|---|---|---|---|---|---|---|---|---|
| low | 42.1 | $0.13 | 45.8 | $0.82 | 42.3 | $0.55 | 46.8 | $2.37 |
| medium | 47.8 | $0.21 | 49.6 | $1.54 | 51.2 | $1.34 | 48.9 | $2.98 |
| high | 50.2 | $0.32 | 50.9 | $1.73 | 53.6 | $1.82 | 51.2 | $3.91 |
| xhigh | 51.0 | $0.39 | 52.4 | $2.31 | 56.0 | $3.46 | 53.2 | $5.98 |
| max | 51.8 | $0.72 | 52.7 | $3.26 | 57.6 | $5.98 | 53.4 | $7.63 |
The system card▶ 7:19
OpenAI's system card for GPT-6.1 Sol is an addendum to GPT-6 Astra's. OpenAI treats Sol as Critical in cybersecurity capability and High in biology and chemistry, the same as Astra, so it gets Astra's safeguards, and advanced security work goes through a separate access program.
On OpenAI's coding-deception test, Sol misrepresented its work in 1.50% of cases, a little more often than GPT-6 Sol at 1.30% and about 2.9× as often as Astra at 0.51%. In a test where a tool is blocked with a warning, Sol tried to get around the block in 23.5% of runs, against 17.4% for Astra. OpenAI's launch chart for the same test, all at max, puts GPT-6 Sol at 64.4%. And in OpenAI's simulation of 49,650 internal Codex tasks, GPT-6.1 Sol drew 28 flags at OpenAI's most serious levels, for misaligned behaviour a reasonable user would strongly object to. GPT-6 Sol drew 42, so that's a third fewer (33% by OpenAI's count), and Astra drew 27.
Three of OpenAI's own evaluations
From the system card addendum for GPT-6.1 Sol
| evaluation | GPT-6.1 Sol | GPT-6 Sol | GPT-6 Astra |
|---|---|---|---|
| coding deception, misrepresentation rate | 1.50% | 1.30% | 0.51% |
| kept going past a warning (a blocked tool) | 23.5% | 64.4% | 17.4% |
| the most serious flags in a simulation of internal Codex tasks | 28 | 42 | 27 |
These are all OpenAI's own tests, and they don't say how often any of it happens in normal use.
What it costs you▶ 8:17
If you pay per token, that quarter is what you'd see at matching scores, and it comes from cheaper tokens and fewer of them. Take Sol at high and Opus at medium, $0.32 against $1.34 a task. At Sol's prices per token, Opus's task would cost $0.67. The rest of the gap is Sol using fewer tokens, weighted by what each kind of token costs.
OpenAI's model page adds some small print. With Sol, a prompt over 272K input tokens costs 2× as much for input and cached input and 1.5× as much for output, for the whole request.
If you pay with a plan, the two aren't on the same meter. Opus draws on a Claude plan and Sol on a ChatGPT one, so there's no common unit to compare them in. OpenAI estimates 15–160 Codex messages per five hours on the Plus plan with Sol, against 5–45 with Astra. When we checked on 30 September, we hadn't found a published measurement of how fast Sol actually uses up a plan.
Should you switch?▶ 9:01
If you're on GPT-6 Sol, try this one first on your own work. If you use Astra in Codex, try Sol. And if you're on Opus 5.5, Sol is worth trying on your own tasks for questions over documents, for tool workflows where Opus at medium is good enough, and for coding agents where a few points matter less than the bill. On those three, Artificial Analysis's figures put Sol at less than half the API cost of Opus.
Cost per task on single tests
GPT-6.1 Sol against Opus 5.5, as Artificial Analysis prices each test
| test | GPT-6.1 Sol | Opus 5.5 | Sol's share |
|---|---|---|---|
| GDP.pdf, Sol at high, Opus at medium | $0.35 | $0.80 | 0.44 |
| GDP.pdf, both at high | $0.35 | $0.83 | 0.42 |
| GDP.pdf, both at medium | $0.34 | $0.80 | 0.42 |
| AutomationBench, Sol at high, Opus at medium | $0.23 | $0.64 | 0.35 |
| AutomationBench, both at medium | $0.20 | $0.64 | 0.31 |
| Coding Agent Index, Sol at xhigh, Opus at max | $1.04 | $13.04 | 0.08 |
For finished work that someone will judge, long projects and the hardest questions, stay on Opus.
Hold all of this loosely, though. Artificial Analysis is still the only independent measurement of GPT-6.1 Sol we've found. When we looked on 30 September, LMArena was still collecting votes and showed no rating, Vals and METR didn't list it, and the SWE-bench and LiveBench pages we saved didn't load their tables, so we can't say either way for those two. GPT-6 Sol scored well on Artificial Analysis too, then spent its week on r/codex being called slow and not very good.
GPT-6 Sol's week on r/codex
Post titles about GPT-6 Sol, the model before this one
| post | points |
|---|---|
| GPT 6 - Sol is an Idiot | 335 |
| GPT-6 Sol is... not good | 145 |
| GPT-6 Sol: 33 minutes to do what GPT-5.6 Sol did in 38 seconds — what is going on? | 23 |
What would settle it is how fast Sol drains a plan, how it does on your own code, and whether people still like it in a week.
Just before this video, we looked at Fireworks' Ember-1, a retrained Kimi K3 that promises the same work with fewer tokens. That's our previous video.